

Geospatial intelligence, or GEOINT, is the collection, analysis and interpretation of imagery and location data to explain what is happening on a piece of ground and why it matters. Planners have used it for decades to site roads, zone land and model flood risk. Satellite resolution has improved steadily over that period, but the sharper break has come from the models that read the imagery, which now generalise well enough that a city no longer needs a bespoke pipeline for every question it wants to ask.
That shift moves computer vision from a supporting tool to the engine of geospatial intelligence. This article covers what GEOINT looks like in practice today, why vision models carry so much of the load, what agentic computer vision changes about the analyst’s workflow, and where the approach still breaks down.
What Geospatial Intelligence Looks Like Today

A modern urban planning team draws on several streams at once, each with a different refresh rate and a different failure mode:
- Public satellite imagery. NASA and USGS Landsat combined with Europe’s Copernicus Sentinel-2 constellation give near-global land coverage every two to three days at 30-metre resolution through the harmonised HLS product.
- Commercial and drone imagery. Sub-metre capture for corridor surveys, site inspection and post-incident damage assessment.
- Street-level and fixed cameras. Existing CCTV estates, traffic cameras and mobile mapping rigs, which see behaviour rather than land cover.
- LiDAR and photogrammetry. Elevation and structure, handled through point cloud processing and 3D computer vision.
- Sensor and mobility telemetry. GPS traces, loop counters, air quality and weather feeds that give the imagery temporal context.
Acquisition stopped being the constraint some years ago. Hundreds of thousands of new satellite scenes are added to public archives every week, and most cities already own more camera footage than they can review. The binding constraint is interpretation capacity.
Why Computer Vision Became the Engine of GEOINT
Until recently, every geospatial question meant a new labelled dataset and a new model. Mapping informal settlements, counting solar installations and tracking construction progress were three separate projects with three separate annotation budgets. Geospatial foundation models collapsed much of that work by pre-training vision transformers on large multi-sensor archives, then exposing reusable representations that a small labelled set can adapt.
Three releases matter for planning teams. NASA and IBM’s open-source Prithvi model, trained on harmonised Landsat and Sentinel-2 data, was run in orbit in 2026 by an Adelaide University and SmartSat CRC team, on both the Kanyini satellite and a payload aboard the International Space Station, making it the first geospatial foundation model deployed in orbit. That matters because it pushes inference toward the sensor rather than the ground station. Clay offers an open alternative with an active community. Google DeepMind’s AlphaEarth Foundations takes a different route again, publishing precomputed 64-dimensional embeddings for every 10-metre pixel of land and coastal water, refreshed annually back to 2017, so a planner can cluster or classify without training a backbone at all.
The practical effect is that the modelling question becomes a data question, since the underlying vision tasks are now largely solved building blocks.
| Planning Question | Primary Signal | Core Vision Task |
|---|---|---|
| Where is the city growing informally? | Multi-year satellite embeddings | Change detection and semantic segmentation |
| Which assets are deteriorating? | Drone and vehicle-mounted imagery | Object detection, for example, pothole detection |
| How do people actually use this street? | Fixed cameras | Tracking and movement heat maps |
| Where is heat, vegetation, or water stress concentrated? | Thermal and multispectral imaging | Pixel-wise regression and classification |
Agentic Computer Vision Changes the Analyst’s Workflow
Detection alone produces findings that still need a human to chase down. A conventional pipeline has its sequence fixed in advance by an engineer: this imagery, this model, this threshold, this output. Agentic computer vision moves that control flow into the system itself. The team states a goal, and the system decides which data to pull, which perception model to apply, whether the first result is good enough, and what to do when it is not.
Three capabilities make that possible. Foundation models supply general representations that transfer across tasks, so the agent has useful tools to reach for. Promptable object detection lets it query for something like tarpaulin-covered stockpiles without anyone having trained that class in advance. Language models supply the planning and the write-up. For a planning authority asking whether a drainage upgrade reduced surface flooding, the result looks closer to this:
- Interpret the request and identify the relevant catchment boundary and time window.
- Select and pull the appropriate imagery, choosing radar over optical where cloud cover would defeat the analysis.
- Run segmentation across before and after periods, then quantify the change in inundated area.
- Cross-check the result against rainfall records to rule out a milder season as the explanation.
- Return a short written finding with the supporting evidence attached, and flag the two sub-areas where the result contradicts the expected outcome.
Steps one and five depend on vision-language models, which is why natural language querying of geospatial archives has moved so quickly. It also explains the current direction of travel toward visual general intelligence, where the same system handles satellite tiles, drone footage, and CCTV without task-specific rewiring.

Why Geospatial Work Suits an Agentic Approach
Urban planning questions tend to have the shape that agentic systems handle well:
- The data is heterogeneous. Answering one question often means combining satellite tiles, a drone survey, a camera feed, and a spreadsheet of permits, each in a different format and coordinate system.
- Source selection is a judgement call. Optical imagery is useless under cloud, thermal is useless at the wrong time of day, and a fixed pipeline cannot make that substitution on its own.
- The real questions are causal. Planners rarely want a count. They want to know whether an intervention worked, which requires a comparison, a control, and a check against confounding factors.
- Iteration is normal. The first result usually raises a second question, and the cost of a human running that loop is why most of those questions go unasked.
What Has to Be in Place Before a Planner Relies on It
Planning decisions are statutory, publicly consultable and often appealed, so a finding that cannot be traced back to its evidence is worth very little. Any agentic deployment needs to log which imagery, model version and intermediate outputs produced a given conclusion, and to surface its own uncertainty rather than reporting a confident number. That argues for explainable AI practices at the reporting layer and a human-in-the-loop holding sign-off on anything that feeds a decision. Used that way, the value for a department with two GIS analysts and a long backlog is throughput on questions that previously never got asked.
Where Cities Are Getting Measurable Value
The strongest deployments tend to be narrow, tied to an existing decision and measured against a baseline the organisation already reports:
- Traffic and mobility. Junction-level analytics, vehicle counting and automatic number plate recognition feeding signal timing and low-emission zone enforcement.
- Kerbside and parking. Parking occupancy detection replacing manual occupancy surveys that were previously run once a year.
- Asset inspection. Automated review of pavement, bridge and lighting condition, which turns reactive maintenance into a ranked programme.
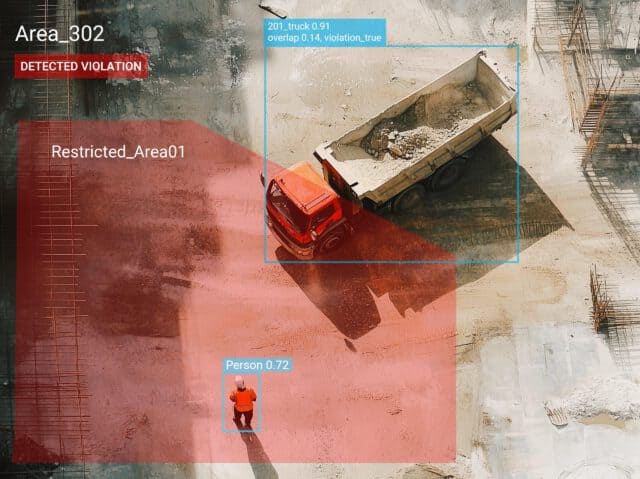
- Construction and delivery oversight. Progress verification and safety monitoring on public works, covered in more depth in our work on computer vision in construction.
- Public space and events. Occupancy and dwell analysis supporting crowd safety planning without identifying individuals.
Our guidance on computer vision in smart cities and our smart city solutions pages show how these threads connect.
The Edge Layer Matters More Than the Model Choice
Satellite analysis tolerates latency. Street-level analysis usually does not, and backhauling continuous video to a central cluster is expensive and often blocked by data protection policy. Running inference locally through edge computing for computer vision on suitable edge devices keeps raw footage on site and sends only structured events onward. Prithvi’s deployment in orbit is the same principle applied one layer further out, and it sits alongside the wider move toward physical AI systems that perceive and act in place.
What Still Limits These Programmes
- Label scarcity in the places that need it most. Foundation models reduce the requirement but do not remove it, and coverage remains uneven in rapidly growing cities.
- Drift. Seasonal change, new construction, and camera repositioning all degrade accuracy over time. Monitoring for concept drift and data drift is not optional in a system meant to run for years.
- Resolution and cost trade-offs. Higher spatial and temporal resolution improves precision and raises storage and compute cost in step with it.
- Governance. Public sector deployment in Europe now carries documentation and risk classification duties under the EU AI Act, and privacy expectations for street-level capture are tightening everywhere.
- Evaluation discipline. A model that reports strong aggregate metrics can still fail on the minority classes a planner cares about, which is why model performance needs to be assessed per class and per site.
A Workable Sequence for Getting Started
- Pick one decision that is currently made on stale or sampled data, and write down the baseline number.
- Inventory the imagery and camera coverage you already own before buying anything new.
- Prototype against open embeddings or an open foundation model, so the first milestone is a result rather than a training run.
- Decide the split between edge and central processing on the basis of latency and data protection, not hardware preference.
- Instrument drift monitoring and per-class accuracy from the first deployment, then expand to a second use case on the same platform.
