

Over the past decade, the field of computer vision has evolved greatly. What began as a niche area within artificial intelligence is now embedded across industries, as cameras have become active systems interpreting visual information from images and videos in real time.

This computer vision progression has been driven by advances in deep neural networks, particularly convolutional neural networks (CNNs). These enabled machines to recognize objects, detect patterns, and extract meaning from complex environments. Tasks that once seemed out of reach, such as object detection in dynamic environments, are now a reality.
But despite this progress, one thing has become clear: seeing is not the same as understanding. And that distinction defines what we’ve truly learned over the last ten years.
Visibility Has Been Scalable, but Not Actionable
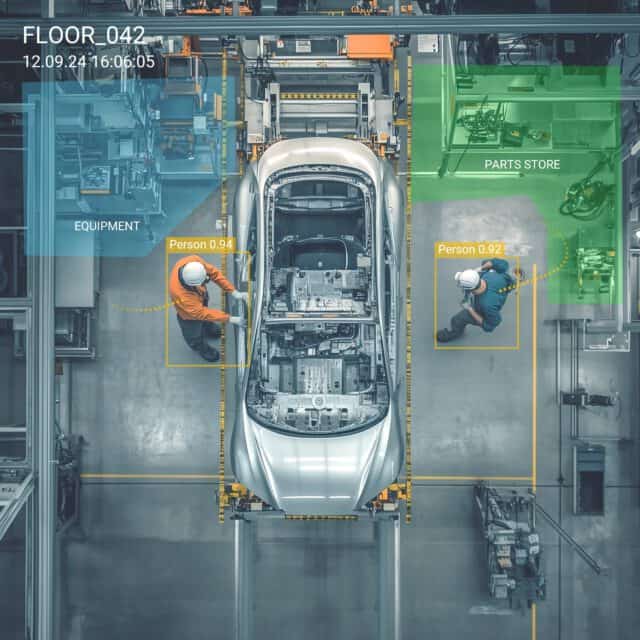
The first major breakthrough was obvious: object detection. Being able to automatically identify objects, people, and behaviors in video streams changed what was possible.

Instead of relying on manual supervision, teams could now detect:
- PPE compliance issues
- Unauthorized access to restricted areas
- Unsafe proximity between people and machinery
These computer vision algorithms focused heavily on image processing and pattern recognition. These systems were effective in controlled environments, where inputs were predictable and variability was limited. Over time, however, the introduction of CNNs and large-scale training data changed the landscape.
Computer vision systems became capable of handling messy, unstructured data from the real world. They could interpret images and videos at scale, power object detection models, and support applications like monitoring industrial environments.
This shift expanded the scope of computer vision tasks significantly, as the focus became understanding scenes, behaviors, and interactions.
Bring a new AI vision application to life.
Hardcoded Systems Hit Their Limits Faster Than Expected
To make detection useful, most computer vision systems evolved by adding more predefined use cases. If a team needed a new insight, it meant building or configuring something new. Over time, this led to systems that looked comprehensive but were actually quite rigid. They could answer a growing number of questions, but only the ones that had already been anticipated.
This worked relatively well in controlled environments when the problem was well-defined, but, of course, operations rarely stay static.
This is where we’ve started to see hardcoded approaches start to break down, as they require too much effort to adapt, and they slow down exactly when teams need to move faster. One of the clearest lessons from the past decade is that flexibility matters more than coverage, emphasizing the value of a system able to quickly undertake new use cases.

More Data Doesn’t Automatically Lead to Better Outcomes
One of the most underestimated challenges in computer vision is what happens after deployment. Teams often expect incremental insight, but in reality, they get a flood of information. This can look like dozens, sometimes hundreds, of detections per day and a constant stream of potential risks and deviations.
At first, this feels like progress as it essentially confirms that the system is working and proves that issues exist. But it can quickly feel overwhelming. When everything is visible, everything can feel urgent. And when everything feels urgent, prioritization becomes difficult. Teams end up reacting inconsistently, or not at all.
This is the paradox that has quietly shaped many deployments: **the more you see, the harder it becomes to decide what matters**.
Dashboards Helped, but Didn’t Solve the Core Problem
To manage this growing volume of information, organizations turned to dashboards. Aggregating detections into trends, heatmaps, and KPIs made the data easier to digest.
Dashboards became the standard interface for computer vision systems. They provided summaries, highlighted patterns, and gave leadership a way to track performance. But dashboards have a limitation that becomes more apparent over time: they are designed to answer predefined questions. They can tell you what happened, how often, and where. But they struggle to answer deeper, more investigative questions, especially when those questions change.
Operational teams need to be able to explore: following threads, comparing scenarios, and understanding context. And that’s where static reporting starts to fall short.
Context is What Turns Data Into Understanding
A detection in isolation is just an event and meaning depends entirely on context. Is this happening repeatedly in one location, or sporadically across many? Did it start after a process change? Is it tied to a specific shift or condition?
These are the kinds of questions that define real operational insight, which are difficult to answer when systems are built around isolated detections and fixed reports. This is why, even with advanced computer vision systems in place, many teams still rely on manual investigation. They review footage, talk to operators, and piece together narratives.
The technology shows *what* happened. Humans are still responsible for figuring out *why*. That division of labor has been one of the biggest limitations of the past decade.

The Next Phase is About Interaction, Not Just Automation
Looking back, the trajectory of computer vision has been clear: from manual observation to automated detection, from limited visibility to continuous monitoring.
But the next step is to build interaction on top of automation. This will look like moving away from systems that deliver predefined outputs to systems allowing teams to ask questions and explore data directly. Instead of navigating dashboards or waiting for new features, teams can investigate in real time:
- Where are we seeing the highest concentration of risk?
- What changed in the past two weeks?
- Are similar patterns happening at other sites?
This shift has a name. Visual General Intelligence, VGI, is what computer vision becomes when it moves beyond detection and into reasoning. Where traditional CV systems answer the questions they were built to answer, a VGI system understands the environment well enough to answer questions it was never explicitly programmed for. It infers context. It draws comparisons across sites and time periods. It surfaces what matters without needing to be told what to look for first.
Computer vision will become less about generating alerts and more about supporting decision-making, also changing who can use it. When systems are flexible and queryable, domain experts can drive the analysis themselves. This is a pretty sizable shift away from the model-centric approach that has defined the last decade, and VGI is what that shift looks like in practice.
What This Means For Operations Teams
The last ten years have proved that computer vision can scale visibility, and the next ten will be defined by whether it can scale understanding.
For HSE, QA, and operations teams, leaders must consider moving beyond thinking of VGI as a monitoring tool. It needs to become part of how teams investigate problems, prioritize risks, and improve processes, which also means rethinking success.
Success is not how many detections a system produces. It’s how effectively teams can use those detections to drive change; measured in reduced incidents, improved processes, and faster decisions. That requires a different approach emphasizing clarity over volume, flexibility over rigidity, and action over observation.
A Decade of Computer Vision: Progress With a Clear Path Forward
Computer vision has come a long way, but the real value comes from what happens next: how teams interpret, prioritize, and act on what they see with Visual General Intelligence.
And that’s where the next phase of innovation is focused, which will define the next decade of computer vision.