

This guide covers how an image classification model works, which machine learning models are used for classifying images, and where classification sits inside the newer generation of agentic vision systems.
What Is Image Classification?
Image classification assigns a class label to an image as a whole, based on the patterns contained in its pixels. The label can be derived from color, texture, spectral response, or, in modern systems, from abstract features the model has learned on its own.
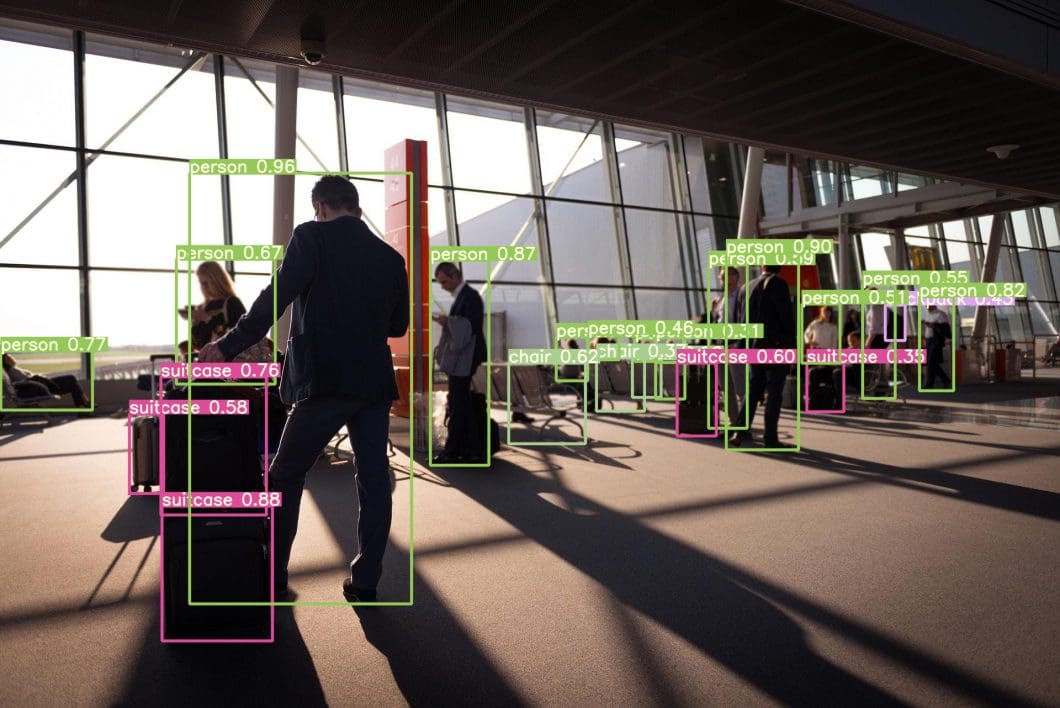
The distinction that matters most in practice is scope. Classification describes the whole frame, while object detection localizes individual instances with bounding boxes and image segmentation labels every pixel. Because classification is the cheapest of the three to train and run, it is often the correct starting point for a first deployment, and it is the reason it sits at the base of nearly all computer vision pipelines.
Bring a new AI vision application to life.
Types of Image Classification
Teams often describe their problem as “image classification” when they mean one of several distinct formulations. Naming the right one determines the loss function, the label schema, and the metrics used to judge success.
- Binary classification: the model chooses between two mutually exclusive outcomes, such as pass or fail on an inspection station. Binary classification is the simplest setup and often the most robust, because a small annotated dataset can support it.
- Multiclass classification: the model selects exactly one label from three or more options, for example identifying which of eight product variants is on a conveyor. Multiclass classification assumes the classes cannot co-occur.
- Multilabel classification: several labels may apply at once, such as an image tagged both “wet floor” and “obstructed walkway.” Each label is scored independently.
- Hierarchical classification: labels are nested, so a coarse prediction narrows the candidate set for a finer one. This suits taxonomies with hundreds of categories.
These types of image classification are not interchangeable, and mismatches between the formulation and the operational question are a common cause of models that test well and then disappoint once installed.
A model can only be as coherent as its label schema. Before any training begins, every class should be defined so that two independent annotators, given the same image, would choose the same label.
How an Image Classification Model Works
A computer reads an image as an array of numbers, with dimensions set by resolution and channel count. Turning that array into a label happens in two conceptual stages, whether the system is a decades-old statistical classifier or a modern network.
Feature Extraction
The first stage is feature extraction, which reduces raw pixels to a compact representation that carries the discriminative information and discards the rest. Classical pipelines used hand-designed descriptors built by engineers with domain expertise. Deep learning replaced that step with representations learned directly from data, which is the single biggest reason accuracy improved so sharply after 2012.
The second stage is the classifier itself, which maps that representation to class scores. Everything downstream, including how well the model generalizes, depends on the quality of the extracted features, so feature extraction deserves more scrutiny than it usually receives.
Supervised and Unsupervised Approaches
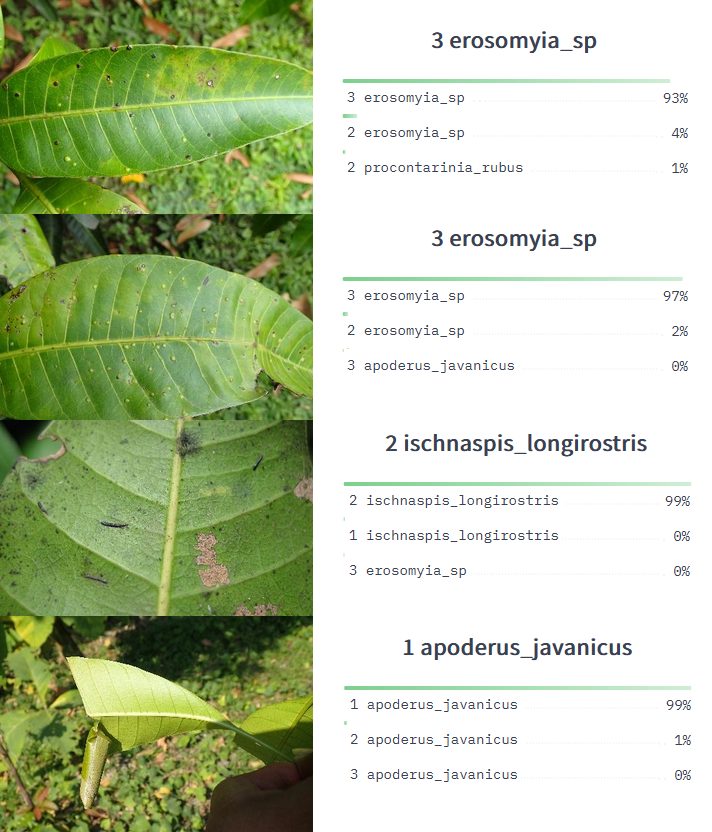
Most production systems rely on supervised learning, in which a labeled training dataset teaches the model the mapping from images to classes. The alternative is unsupervised clustering, which groups images by similarity without human labels and is useful for exploratory work, for organizing an unlabeled archive, or for pattern recognition where the categories are not known in advance.
- K-means partitions samples into a fixed number of clusters based on distance in feature space. The cluster count must be specified in advance.
- ISODATA, short for Iterative Self-Organizing Data Analysis Technique, extends the same idea by splitting and merging clusters across iterations, so the final number of groups is not fixed at the outset.
For a fuller treatment of the tradeoffs, see our overview of supervised versus unsupervised learning.
Classical Machine Learning Approaches
Before deep networks, image classification tasks were handled by general-purpose machine learning algorithms applied to hand-engineered features. These methods have not disappeared. They remain competitive when data is scarce, when inference must run on very constrained hardware, or when a decision needs to be auditable.
| Approach | How It Learns | Best Suited To |
|---|---|---|
| Support vector machines | Finds the boundary with the widest margin between classes in a transformed feature space | Small datasets, clean binary problems |
| Decision trees and ensembles | Splits data on feature thresholds in sequence, often aggregated across many trees | Tabular features, cases requiring interpretability |
| Maximum likelihood and minimum distance | Assigns pixels using statistical distributions or distance to class means | Remote sensing and multispectral imagery |
| Convolutional neural networks | Learns hierarchical features and the classifier jointly from labeled data | Large datasets, complex or cluttered scenes |
Support vector machines were introduced by Cortes and Vapnik in their 1995 paper on support-vector networks, which framed the two-group classification problem in terms of margin maximization. Decision trees, and the ensemble methods built on them take a different route by learning sequences of threshold rules, which makes their predictions easier to explain to a safety or quality team.
Convolutional Neural Networks and Deep Learning Models
Convolutional neural networks reshaped the field by learning features and classification weights in a single optimization. A CNN applies small learned filters across the image, so early layers respond to edges and textures while deeper layers respond to increasingly abstract structure.
Why the Shift Happened
The turning point came in 2012, when AlexNet won the ImageNet Large Scale Visual Recognition Challenge. Trained on roughly 1.2 million labeled examples across 1,000 categories, the network reported a top-5 test error rate of 15.3 percent against 26.2 percent for the runner-up, a margin documented in the original NeurIPS paper. The benchmark itself, and the annotation methodology behind it, are described in the ILSVRC overview paper.
That result opened a decade of architectural work, including VGGNet, GoogLeNet, ResNet, and DenseNet, and it established ImageNet as the reference training dataset for pretraining. Deep learning models now reach high accuracy on specific classification tasks that were considered unsolvable twenty years ago, though that accuracy is always conditional on the data they were trained with.
CNN Layers
Depth is what the word “deep” refers to, and a network may stack anywhere from a handful to well over a hundred layers. Four layer types do most of the work.
- Convolution layer: applies learned filters across the input to produce feature maps.
- Activation layer: introduces nonlinearity, most commonly through a rectified linear unit, allowing the network to represent complex functions.
- Pooling layer: downsamples feature maps, reducing computation and adding tolerance to small shifts in position.
- Fully connected layer: flattens the learned representation and produces the final class scores.
Regularization techniques such as dropout and batch normalization address overfitting, which is the tendency of a large model to memorize its training data rather than learn generalizable structure. More recently, vision transformers have matched or exceeded CNNs on large-scale benchmarks by replacing convolution with attention over image patches.
Building a Training Dataset That Survives the Real World
The most common reason a classifier underperforms after deployment has nothing to do with architecture. It is the training dataset. A model trained on clean, well-lit, centered images will fail on a shop floor where the same object appears partially occluded, motion-blurred, and lit by a mix of daylight and sodium lamps.
Several practices make the difference between a demo and a system that holds up in the real world:
- Collect images from the actual cameras, mounting positions, and shift patterns the model will face in production.
- Audit class balance early and correct it through targeted collection rather than through aggressive oversampling alone. Our guide to model training errors covers the failure signatures to look for.
- Hold back a test set that reflects deployment conditions, and evaluate with precision and recall rather than accuracy alone when classes are imbalanced.
- Plan for drift. Seasonal light, equipment changes, and new product lines all shift the input distribution over time, so retraining should be scheduled rather than reactive.
Classification Inside Agentic Computer Vision
Classification used to be the end of the pipeline. A model emitted a label, a rule fired, and a human read a dashboard. That arrangement is changing.
In agentic computer vision, classification becomes one signal among many that an agent reasons over. The agent can decide which model to invoke, escalate an uncertain frame to a heavier model or to a human reviewer, correlate a classification result with other sensor data, and take an action rather than simply reporting one. A lightweight classifier running continuously at the edge, paired with an agent that only invokes expensive analysis when the label is ambiguous, is a far more economical design than running a large model on every frame.
This is also why edge AI and classification are so closely linked. Small classification models are cheap enough to run on edge devices next to the camera, which keeps latency low and keeps raw video from leaving the site.
Applications of Image Classification
Classification is deployed wherever a categorical judgment about a whole frame carries operational value:
- Automated inspection and defect detection on production lines
- Triage of medical imaging studies to prioritize radiologist review
- Crop and disease classification in agriculture
- Land use and land cover mapping from satellite imagery
- Document and form sorting through optical character recognition pipelines
- Condition assessment of infrastructure and equipment
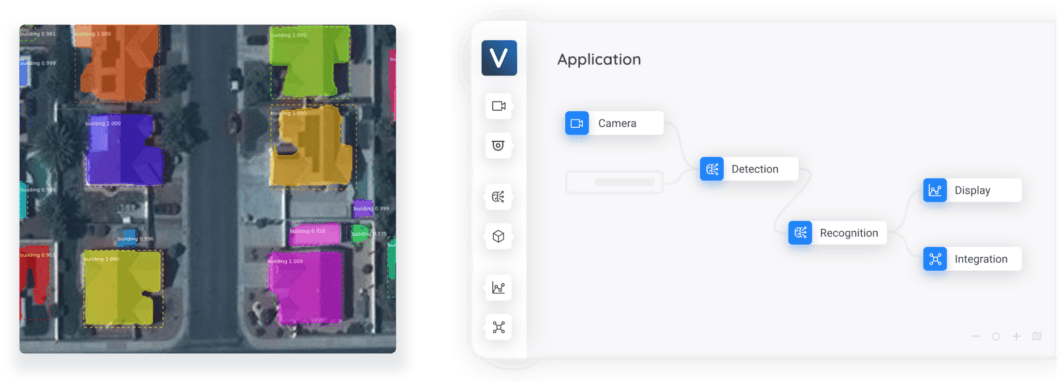
Teams building these systems on Viso Suite typically start with a narrow classification problem, prove the value, then extend into detection and tracking once the data pipeline is stable.
The Bottom Line
Image classification is mature technology, and that maturity is exactly why it is worth getting right. The architecture choice matters less than a well-specified label schema, a training dataset drawn from real operating conditions, and honest evaluation on data the model has never seen.
The more interesting question now is what sits above the classifier. As agentic systems take on the work of deciding which model to run and what to do with the result, classification stops being a final answer and becomes a fast, cheap signal inside a larger reasoning loop.
Explore related reading: