

MediaPipe is an open-source framework from Google for building pipelines that run computer vision and machine learning inference over streaming sensory data such as video, audio, and time series signals. Rather than treating a model as a single black box, MediaPipe treats perception as a graph of modular components that can be rearranged, replaced, or extended.
The framework has evolved considerably since its early alpha releases. What was once a collection of standalone demos is now organized under a broader umbrella called MediaPipe Solutions, which packages pre-trained models, cross-platform runtimes, and customization tooling into one product family.
What Is MediaPipe and Why Does It Matter?
At its core, MediaPipe answers a specific engineering problem: how do you run perception models at real-time frame rates on hardware that has limited power and thermal headroom? Cloud inference introduces latency and bandwidth costs that many applications cannot absorb, which is why on-device machine learning has become the default expectation for interactive vision features.
The framework was designed for AI and ML engineering teams shipping production features, as well as researchers who need reproducible prototypes. The original architecture is documented in the MediaPipe research paper, which describes the graph-based approach in detail.
MediaPipe operates at a higher level of semantics than a single neural network. One input frame can produce zero, one, or many outputs, a behavior that a fixed input-output model cannot express on its own.

Bring a new AI vision application to life.
Features of MediaPipe
The features of MediaPipe that matter most in production come down to four properties:
- End-to-end acceleration. Inference and media processing are accelerated on commodity CPU, GPU, and TPU hardware without bespoke engineering for each target.
- Build once, deploy widely. The same graph definition can target Android, iOS, desktop, web, and edge devices.
- Pre-trained solutions. Ready-made pipelines cover the most common perception tasks, so teams start from a working baseline rather than a blank file.
- Open source licensing. The framework is released under Apache 2.0, fully extensible, and inspectable.
MediaPipe Solutions: Tasks, Model Maker, and Studio
MediaPipe solutions are grouped into three layers, and understanding the split makes the documentation far easier to navigate.
MediaPipe Tasks
MediaPipe Tasks is the runtime API. It exposes a small set of methods per task, handles preprocessing and postprocessing internally, and returns structured results such as a bounding box, a set of landmarks, or a classification score. Language bindings cover Android, iOS, Python, and web, which means a single task definition travels across the full deployment surface.
MediaPipe Model Maker
MediaPipe Model Maker handles customization. It applies transfer learning to retrain a supported architecture on your own labelled data, then exports a package that Tasks can load directly. For teams that need a domain-specific detector but lack the data volume to train from scratch, this is the shortest viable path.
MediaPipe Studio
Studio is the browser-based evaluation surface. It lets you benchmark candidate configurations against sample media before writing integration code, which shortens the loop on model performance comparisons.

MediaPipe Models and Vision Capabilities
The available MediaPipe models cover a focused range of perception problems. Most ship as TensorFlow Lite assets, which keeps binary size and inference cost low enough for mobile deployment.
| Task | What It Returns | Typical Real-Time Use |
|---|---|---|
| Face detection | Bounding box plus key points | Framing, auto-exposure, anonymisation |
| Face landmarker | Dense face landmarks and blendshapes | Face mesh effects, expression tracking |
| Hand landmarker | Per-hand keypoints in 3D | Hand tracking and gesture control |
| Pose estimation | Full-body skeletal landmarks | Form analysis, ergonomics, motion capture |
| Object detection | Class labels with a bounding box each | Counting, tracking, scene inventory |
| Image segmentation | Per-pixel masks | Background replacement, region isolation |
The face mesh pipeline is worth singling out. It estimates hundreds of face landmarks from a single camera feed, and it does so without depth hardware. The pose model follows a similar design philosophy, where a lightweight detector primes a heavier landmark model that then tracks across frames.
Detection hand pipelines work the same way. A palm detector localizes the region, and a landmark model refines it, giving stable hand tracking even when fingers occlude one another.
How to Get Started With MediaPipe
For Python, installation is a single command:
pip install mediapipeFrom there, most tasks require fewer than twenty lines to produce output on a webcam feed. Android, iOS, and web developers use the equivalent platform packages, and teams needing custom calculators can still drop down to the C++ layer. Source and platform guides live in the MediaPipe GitHub repository.
- Prototype in Python. Fastest feedback loop for validating whether a pre-trained model fits your data.
- Customize with Model Maker. Retrain only when the stock model measurably underperforms on your footage.
- Port to Android or iOS. The task API surface is consistent, so integration work is mostly UI plumbing.

From Perception Pipelines to Agentic Computer Vision
A MediaPipe graph is deterministic by design. It ingests frames, emits landmarks or boxes, and stops there. The interesting question for the next generation of systems is what consumes that output.
Agentic computer vision systems treat structured perception output as evidence for reasoning rather than as a final answer. A hand tracking stream becomes a signal about task compliance. A pose sequence becomes a hypothesis about ergonomic risk. When paired with vision language models, these signals can be queried in natural language, and the system can decide which cameras to attend to next.
MediaPipe fits that architecture as a fast, cheap perception layer. It supplies the geometric primitives; the agentic layer supplies the interpretation and the action. Running both close to the sensor keeps latency and cost predictable, which is the practical argument for edge computing in computer vision.
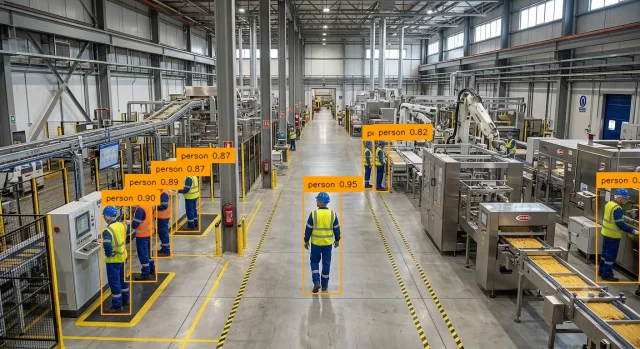
Where a Framework Ends and a Platform Begins
MediaPipe solves inference and pipeline composition well. It does not solve fleet management, versioned rollouts, annotation workflows, access control, or long-horizon monitoring. Those are platform concerns.
The Viso Suite computer vision platform integrates frameworks including MediaPipe and OpenCV, then adds the operational layer around them: data collection, training, deployment across distributed hardware, and continuous monitoring. Teams get the flexibility of open source models with the governance that enterprise deployment requires.
