

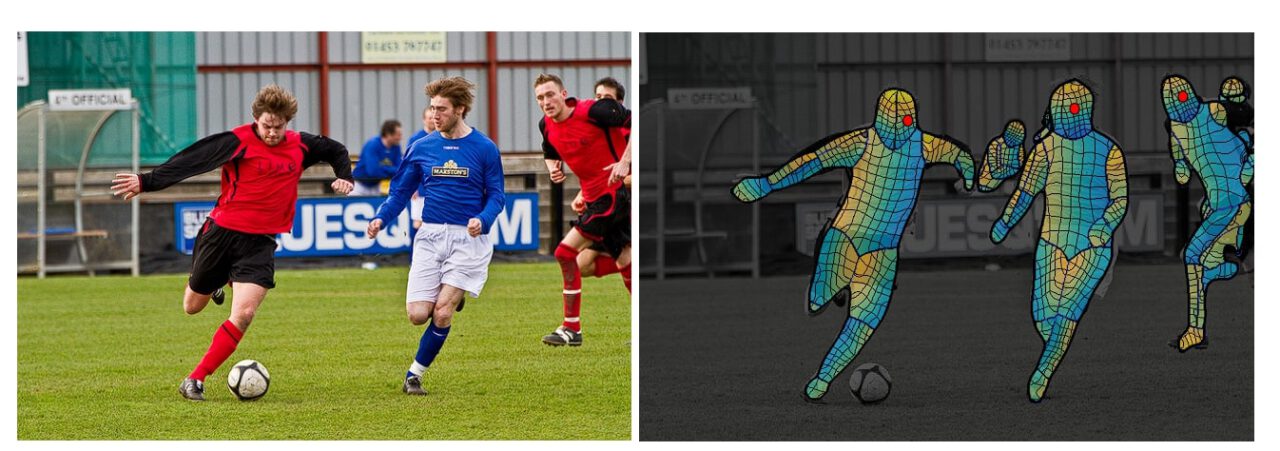
DensePose is a computer vision model that maps every pixel belonging to a person in an ordinary RGB image onto the surface of a 3D body model. That is a fundamentally different task from locating a handful of joints. Instead of returning a skeleton, it returns a surface coordinate for each human pixel, which makes it possible to reason about specific patches of anatomy rather than approximate positions. The model was introduced in 2018 by researchers at Facebook AI Research and INRIA-CentraleSupélec, and it remains the clearest demonstration of dense correspondence treated as a first-class perception task rather than a post-processing step.
What DensePose Actually Predicts
For every pixel inside a detected person, DensePose predicts three values. The first is a chart index that identifies which body part the pixel belongs to. The second and third are U and V coordinates that locate the pixel within that part’s flattened two-dimensional parameterization. Together these are usually written as IUV.
The reference geometry is the SMPL body model, whose surface is partitioned into 24 charts. Each chart is unwrapped so that every vertex carries a unique UV coordinate, which is what allows a prediction to be compared against ground truth on a common surface. Because the parameterization is fixed, the same anatomical point resolves to the same coordinate across different people, camera angles, and frames.
This is the distinction that most explanations of the model blur, so it is worth stating plainly.
A keypoint model answers where a joint is. DensePose answers which patch of body surface a pixel belongs to, and where on that patch it sits. The first gives you a pose. The second gives you a correspondence.
Sparse approaches such as OpenPose and AlphaPose return a fixed set of landmarks, which is sufficient for gesture recognition or gait analysis. Our pose estimation overview covers that family in depth. Dense correspondence supports a different class of question entirely, including surface-level contact reasoning, garment fitting, and texture transfer.
Bring a new AI vision application to life.
Facebook DensePose: Origins and Naming
The phrase Facebook DensePose is widely used because Facebook AI Research published the work, released the reference implementation, and funded the annotation effort. The authorship is more distributed than the name suggests. Rıza Alp Güler was at INRIA-CentraleSupélec, while Natalia Neverova and Iasonas Kokkinos were at Facebook AI Research. The paper appeared at CVPR 2018 and is available in full through CVPR Open Access.
One point of confusion is worth correcting directly, because it circulates in secondary write-ups and in AI-generated summaries.
DensePose was released in 2018, not 2010. The original Caffe2 implementation is no longer maintained, and the supported version now lives inside the Detectron2 repository.
Anyone evaluating the model today should start from Detectron2 rather than the archived standalone repository. The DensePose project inside Detectron2 carries the current architectures, trained weights, and evaluation tooling, and the code there is released under Apache 2.0.
How the DensePose-RCNN Architecture Works
DensePose-RCNN is a variant of Mask R-CNN with an additional head devoted to surface regression. The pipeline runs in a fixed order:
- A backbone built from convolutional neural networks, typically ResNet with a Feature Pyramid Network, extracts multi-scale features.
- A region proposal network inherited from Faster R-CNN generates candidate person regions using anchor boxes and objectness scores.
- RoI Align pools features for each candidate region without rounding coordinates to integer grid positions.
- A fully convolutional head classifies each pixel into a surface chart and regresses local coordinates within that chart.
Why RoI Align Matters Here
Standard RoI pooling quantizes region boundaries to the nearest integer cell, which shifts features by up to half a cell. For object detection that error is usually tolerable. For dense surface regression it is not, because the head is predicting continuous coordinates at pixel granularity. RoI Align removes the quantization step using bilinear interpolation, and the resulting alignment is what makes sub-part precision achievable at all.
Cascading and Task Synergy
The authors improved accuracy by cascading, feeding predictions from related tasks back into the surface head. Keypoint estimation and instance segmentation both share structure with dense correspondence, so their outputs act as complementary supervision. This is a recurring pattern in multi-task computer vision systems, where a weaker signal on an adjacent task sharpens the primary one.

The DensePose-COCO Dataset
The model works because a dataset was built for it. DensePose-COCO extends the COCO dataset with manually annotated image-to-surface correspondences for 50,000 humans, amounting to more than five million annotated points in total.
The annotation pipeline is the genuinely novel contribution, and it is a good case study in human-in-the-loop design. Annotators first segmented visible body parts, then placed roughly equidistant sampled points onto the correct location on the surface. Rather than rotating a 3D mesh, they chose from six pre-rendered views of each part, which collapsed a slow manipulation task into a fast selection task. Annotators were also instructed to estimate the body part beneath clothing, so a loose garment would not corrupt the correspondence.
Coverage is uneven by design. Each annotated person carries only about 100 to 150 labeled points, so the authors trained an inpainting network to fill in supervision values at unannotated positions before training the main model.
There is one constraint that matters more for commercial work than any accuracy figure.
The DensePose-COCO and DensePose-PoseTrack datasets are distributed under a NonCommercial Creative Commons license, even though the Detectron2 code is Apache 2.0. Model weights trained on that data inherit the restriction.

Chart-Based Estimation Versus Continuous Surface Embeddings
The 2018 formulation is now called the chart-based approach, and it is no longer the only option. In 2020, Neverova and colleagues introduced continuous surface embeddings, which learn descriptors for mesh vertices and image pixels simultaneously and then match them, rather than relying on a hand-designed chart partition.
The practical difference is generalization across body types and species.
| Property | Chart-Based (IUV) | Continuous Surface Embeddings |
| Surface representation | 24 hand-designed charts with local UV coordinates | Learned vertex and pixel embeddings, matched at inference |
| Detection meta-architecture | Mask R-CNN with FPN | Faster R-CNN with FPN |
| New categories | Requires a new chart design and annotations | Supports new 3D meshes, including animals |
Detectron2 ships both paradigms, alongside a bootstrapping framework that extends coverage to unlabeled data. For teams working in 3D computer vision, the embedding formulation is usually the better starting point because it does not assume a human topology.
Applications of Dense Correspondence
Dense correspondence earns its extra compute in tasks where a skeleton is too coarse to answer the question being asked:
- Virtual garment fitting. Because every pixel maps to a known surface location, a garment texture can be warped onto a body without a dedicated depth sensor, which is why the technique became common in e-commerce try-on.
- Animation retargeting. Captured human motion transfers to digital characters through surface correspondence rather than joint approximation, reducing the manual cleanup that skeleton-driven pipelines require.
- Biomechanical analysis. Sports science and clinical posture assessment benefit from tracking how surface regions deform, not merely how joint angles change.
- Augmented reality. Body-aware overlays stay anchored to anatomy across movement, since the reference coordinate does not drift when a limb rotates.
- Industrial safety. Surface-level reasoning distinguishes a hand entering a machine envelope from a torso passing nearby, a distinction that bounding boxes cannot make.
Where DensePose Fits in Agentic Computer Vision
Dense correspondence is a perception primitive, not an application. Its value increases when a reasoning layer sits above it and can ask questions of the output. This is the structural argument behind agentic computer vision, where models that produce precise geometric facts are orchestrated by systems that decide what to do with them.
Vision language models and large vision models are strong at describing a scene and weak at metric precision. A surface coordinate is the opposite. Pairing them lets an agent ask whether a specific body region entered a hazardous zone, rather than whether a person appears near it. Combined with person re-identification, the same surface can be tracked across cameras.
Running this at scale is an infrastructure problem more than a modeling one. Viso Suite provides the deployment layer above open-source models of this kind, and edge computing for computer vision is usually where the throughput constraint gets resolved.
Practical Limits of DensePose
The model has real constraints, and several are architectural rather than incidental:
- No metric 3D output. DensePose returns surface coordinates, not a posed mesh in world units. Recovering shape and depth requires fitting a body model on top of the correspondences.
- Compute cost. Throughput falls sharply with input resolution, which pushes high-resolution deployments toward accelerators or downsampling.
- Licensing. The NonCommercial dataset license constrains commercial use of anything trained on DensePose-COCO.
- Domain gap. COCO imagery is consumer photography. Industrial scenes with protective equipment, unusual viewpoints, and heavy occlusion sit outside the training distribution.
- Annotation density. Sparse ground truth caps achievable precision, which is why the inpainting network was necessary in the first place.
