

Somewhere in a logistics facility right now, a supervisor is scrubbing through four hours of yard footage trying to answer one question. A warehouse manager has been waiting 3 days for an analyst to tell her whether her team followed the loading protocol last Tuesday. An operations director is sitting on six months of site video that has never been opened.
The footage exists. The question exists. But the gap between them is what we’re discussing here.
Large vision models are closing this gap, and it’s absolutely vital to understand what they are, how they differ from what came before, and why they matter now is increasingly the difference between organizations that extract intelligence from their visual data and those that sit on it.
What is a Large Vision Model?
A large vision model (LVM) is an AI system trained on vast, diverse datasets of images and video to develop a generalized understanding of visual content, not to recognize one specific thing, but to understand what it is looking at across any context.
Essentially, LVMs understand what they see similarly to how people do (context and reasoning) rather than by matching against a labeled training set.
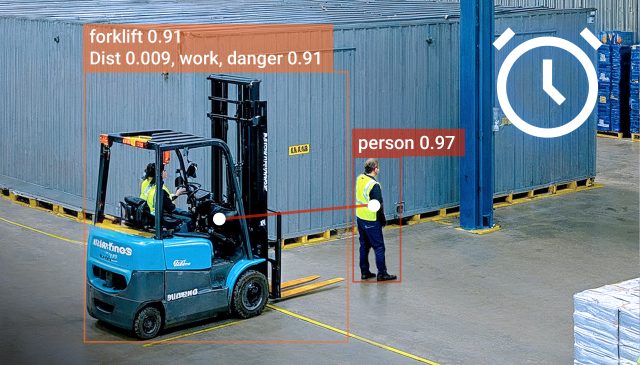
This distinction is worth dwelling on. Traditional computer vision models are trained to perform image recognition of specific objects or events in specific conditions. If you change the lighting, the angle, or the environment, performance can often degrade. Every new use case requires a new model, new training data, and a new deployment cycle.
Large vision models work differently. They learn from scale and diversity rather than from task-specific examples. The result is a model that has encountered enough of the world, warehouses, terrain, construction sites, factory floors, retail environments, and public spaces to understand what is happening in a scene without being told what to look for in advance.
Bring a new AI vision application to life.
LVMs vs. Traditional Computer Vision: What Actually Changes
Traditional CV models are optimized for a task. They are fast, precise, and reliable when the task is clearly defined, the environment is controlled, and the training data is representative. When any of those conditions change, they break. And the fix is always the same: more image data, more annotation, more training, and deploying time.
Large vision models are optimized for understanding. They do not require labeled examples of every scenario they might encounter, as they can reason about novel situations, interpret context, and answer questions about footage they have never seen before.
| Traditional CV Model | Large Vision Model (LVM) | |
|---|---|---|
| Training Required | Yes, labeled data per task | No, zero-shot capable |
| Adapts to new use cases | Requires retraining | Handles without retraining |
| Natural language queries | Not supported | Native capability |
| Context and reasoning | Not supported | Core capability |
| Time to first insight | Weeks to months | Minutes |
While the table makes it look like a clean upgrade, in practice, the shift is more nuanced. Traditional CV still has its place in highly defined, high-throughput inspection tasks where precision and speed are the only requirements. But for the majority of real-world operational questions, involving behavior, context, and interpretation, LVMs represent a structural step forward.
The Architecture That Makes It Possible
Most large vision models follow a vision-language architecture. A vision encoder, typically a transformer-based model (see our article on Vision Transformers ViT), processes image or video data and converts it into numerical representations capturing spatial relationships, object identities, and scene context. A language model decoder then interprets those representations in response to natural language inputs.
The projection layer between them is what makes the interaction possible. It aligns the visual encoder’s output with the language model’s expected input, enabling the system to process a question like “were pedestrians entering the vehicle zone during the night shift?” and map it against video footage without any task-specific fine-tuning.
This architecture is why LVMs are often referred to as vision language models (VLMs) or large vision language models (LVLMs). The terms are used interchangeably across the research literature. The meaningful distinction is between models optimized for understanding and reasoning (the LVM category) versus models optimized for generation or description.
What has changed most significantly in the past eighteen months is edge deployment: compact LVM architectures now run efficiently on local hardware without cloud connectivity, with inference speeds capable of supporting real-time monitoring in environments where data cannot leave the facility. For manufacturing, logistics, and construction applications, this resolves what was previously a hard architectural barrier.

The Main Types of Large Vision Models
The LVM category is broader than a single architecture. Different model types are built for different tasks, and understanding the distinctions matters when evaluating what a platform is actually capable of under the hood.
| Type | What It Does | Enterprise Relevance |
|---|---|---|
| Vision Language Models (VLMs/LVLMs) | Combines a visual encoder with a language model decoder, enabling natural language processing and interaction with visual content | The most directly applicable category for querying footage and answering operational questions in plain language. GPT-4o, Gemini 2.5 Pro, Qwen3-VL |
| Vision Foundation Models | Large-scale models pre-trained on diverse visual data for broad representational learning rather than a specific task | Often the encoder backbone inside larger systems. Strong generalisation across tasks and domains without fine-tuning. CLIP, DINOv2 |
| Video Understanding Models | Reasons across sequences of frames rather than individual images, capturing temporal relationships, motion patterns, and event progression over time | Critical for recorded footage use cases where understanding what happened across a timeline matters as much as what is visible in a single frame. LLaVA-Video, Qwen2.5-VL |
| Segmentation and Spatial Models | Identifies and delineates specific regions, objects, or boundaries within an image or video frame with precision | Underpins use cases where location and boundaries matter: damage assessment, restricted zone monitoring, proximity detection. SAM2 |
| Generative Vision Models | Produces visual content rather than interpreting it | Less directly applicable to operational intelligence, but increasingly used for synthetic data generation and training data augmentation. DALL-E, FLUX |
| Edge-Optimised LVMs | Compact architectures designed to run inference locally on-device without cloud connectivity | Defines which models are viable for industrial environments with data sovereignty, latency, or connectivity constraints. The performance gap with cloud models is closing fast |
For most operational use cases (querying footage, monitoring environments, understanding events in context), vision language models and video understanding models are the most relevant. The distinction between them is worth holding onto: a VLM answers questions about what is in a scene; a video understanding model explains what happened across a sequence of events.
Why LVMs Matter More Than the Technical Community Has Let On
The LVM conversation has largely been a technical one. Benchmarks, parameter counts, AI model comparisons. That framing is accurate but incomplete; it misses the more consequential shift.
For most organizations, the barrier to extracting intelligence from visual data has never been a lack of capable models. It has been the pipeline required to put those models to work:
- Collecting training data
- Annotating that data
- Training and validating a model
- Deploying that model
- Maintaining that model as conditions change
- Rebuilding that model for the next use case
Large vision models perform better on benchmarks and make most of that pipeline unnecessary.
An operations manager who wants to know whether vehicles were following the one-way system during last week’s early shift does not need to commission a model training project. They need to upload the footage and ask the question. A safety manager who wants to understand whether PPE compliance drops during shift handovers does not need an ML engineering team. They need a platform that can interpret the footage and surface the answer.
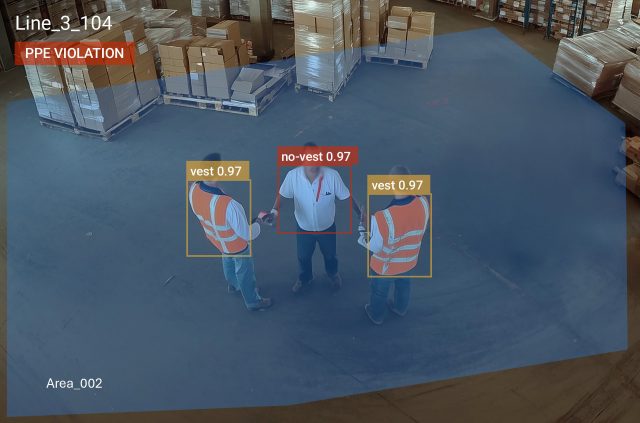
This is the change that matters for enterprise operations: what the architecture finally makes possible for the people who were never going to train a model in the first place.
LVMs and the Shift to Visual General Intelligence
Large vision models are the foundational capability layer beneath a broader category shift that is now underway: the move from narrow computer vision to Visual General Intelligence (VGI).
staging-website.viso.ai/ published the foundational white paper on Visual General Intelligence in early 2025, defining VGI as the leap from task-specific detection to general contextual understanding, a system that infers meaning, reasons across domains, and acts without needing to be trained for each new situation it encounters.
LVMs are what make VGI real. Without the generalized understanding that large vision models provide, VGI is a concept. With them, it is deployable today.
The practical expression of this is not a research paper or a benchmark score. It is the ability to upload a piece of footage, ask a question in plain language, and receive an answer that would previously have required a team, a model, and a timeline. That capability exists now; the question for every organization sitting on unanalyzed video is what they are waiting for.
What LVMs Cannot Do…Yet
Intellectual honesty matters here, and the organizations getting the most out of LVMs are the ones that understand the current boundaries clearly.
For use cases requiring sub-frame precision and dimensional inspection at micron tolerances, for example, task-specific trained models still outperform general LVMs. Where inference speed is the primary constraint and the task is tightly defined, a dedicated narrow model will be faster and cheaper to run at scale.
Real-time continuous monitoring at very high camera volumes also still benefits from purpose-built architecture, though this gap is closing faster than most enterprise technology cycles can absorb.
The practical answer for most organizations is not either/or. The best deployments at this time combine LVM-powered general intelligence for exploratory, contextual, and novel use cases with purpose-built models for the high-throughput, well-defined visual tasks where they remain optimal. The infrastructure that supports both, under the same governance framework, is where the real operational advantage sits.
The Question Every Organization Should Be Asking
Deloitte’s 2025 survey of manufacturing executives found that 28% identified vision systems as a priority investment for the next two years, a figure collected before the current generation of large vision models became practically deployable at enterprise scale.
The organizations moving fastest are not the ones with the largest AI teams or the most sophisticated model development capabilities.
Our What We Learned in a Decade of Computer Vision blog supports this idea. Seeing the environment around you is within arm’s reach, but truly understanding the situation with artificial intelligence is the defining factor.
The footage already exists in most organizations, much of it manually monitored. Hours of it, unanalyzed, sitting on servers and hard drives, recording operational reality that no one has ever been able to interrogate at scale. Large vision models are the reason for these changes, and VGI is what it looks like when the change is operationalized.