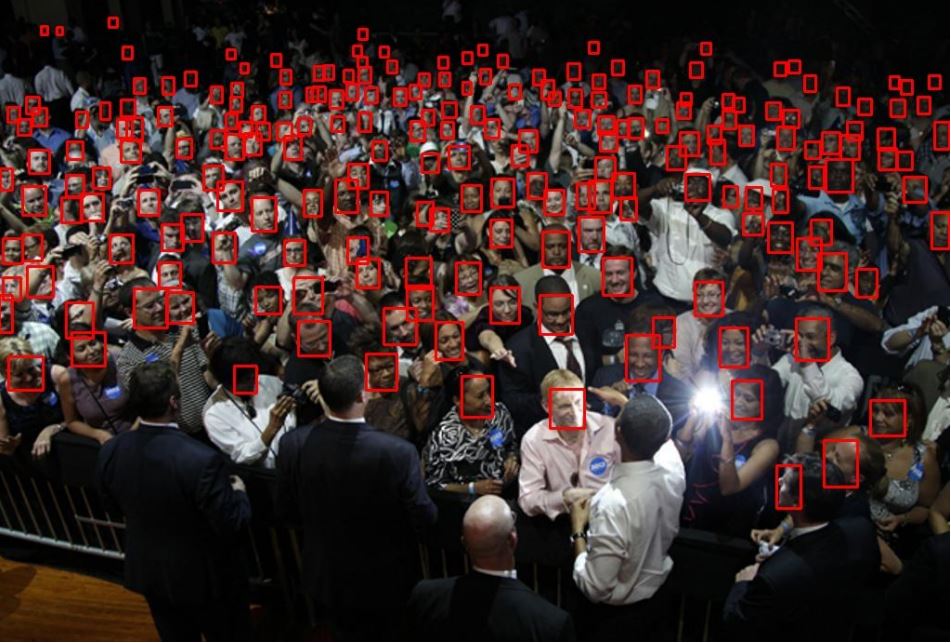
Facial recognition is one of the oldest commercial applications of deep learning, and it is still one of the most misunderstood. Teams compare published accuracy scores, pick the model with the highest number, and then watch performance collapse in production.
DeepFace, the open-source Python library maintained by Sefik Ilkin Serengil, is useful precisely because it makes the whole pipeline visible. It wraps eleven recognition models and twenty detectors behind a handful of function calls, and it publishes reproducible benchmarks that show where accuracy actually comes from.
This guide covers how DeepFace works, what its benchmarks really say, and how it now operates as a tool inside agentic systems.
What Is DeepFace AI?
DeepFace AI is a lightweight face recognition and facial attribute analysis framework for Python, distributed under the MIT License. It is a hybrid framework rather than a single model. Instead of training its own backbone, DeepFace wraps established architectures and standardizes the plumbing around them: detection, alignment, normalization, embedding generation, and distance comparison.
That design choice matters for anyone building production computer vision systems. Swapping a recognition model becomes a one-line configuration change rather than a rewrite. The library handles the preprocessing that usually consumes the majority of engineering time, and it exposes each stage as an argument you can tune.
DeepFace covers four primary tasks:
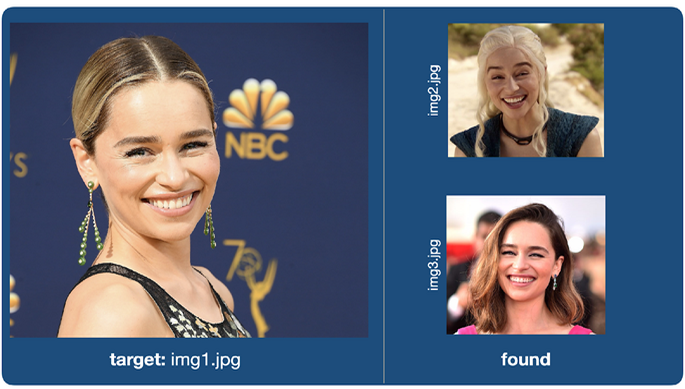
- Face verification: comparing two images to determine whether they show the same person, which is the standard approach for matching a live capture against an identity document.
- Face recognition: searching a database of known identities for a match, implemented as face verification applied many times.
- Facial attribute analysis: predicting age, gender, emotion, and race or ethnicity from detected facial features.
- Real-time analysis: running recognition and attribute analysis against a live webcam or video stream.
The library is available on PyPI and installs with a single pip command, which is a large part of why it has become the default starting point for facial recognition prototypes.
Bring a new AI vision application to life.
The Five Stages of a Facial Recognition Pipeline
A modern facial recognition pipeline is a sequence, and every stage compounds the errors of the one before it. DeepFace documents five:
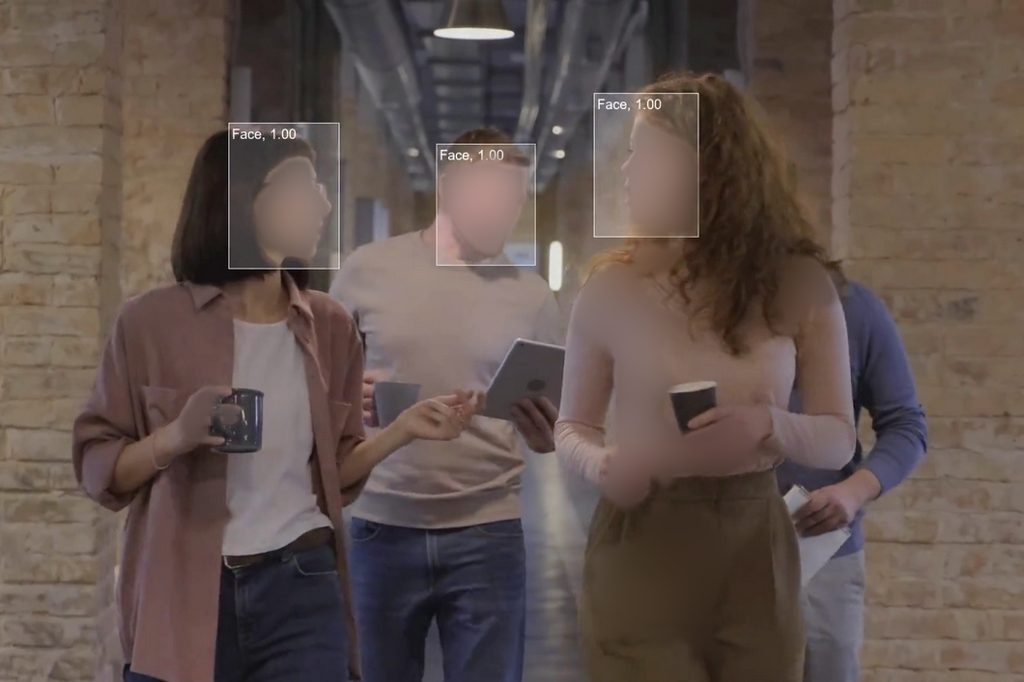
- Detect. Locate faces within the frame and return bounding boxes.
- Align. Rotate each detected face to a canonical orientation using eye landmarks.
- Normalize. Resize and scale pixel values to match the expectations of the target model.
- Represent. Pass the prepared face through a network to produce a verification embedding, a fixed-length vector encoding identity.
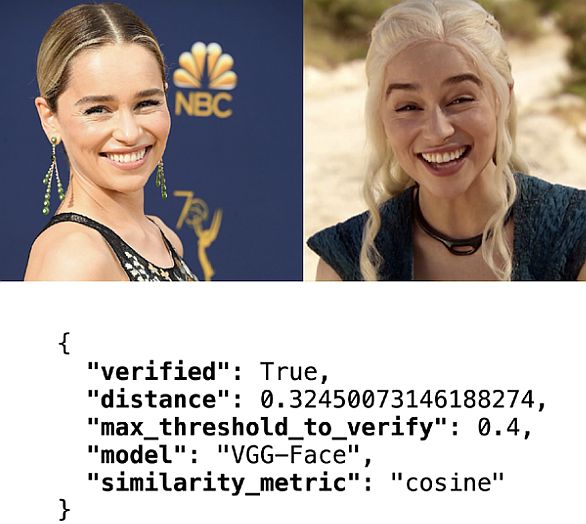
- Verify. Compare two embeddings using a distance metric and apply a threshold.
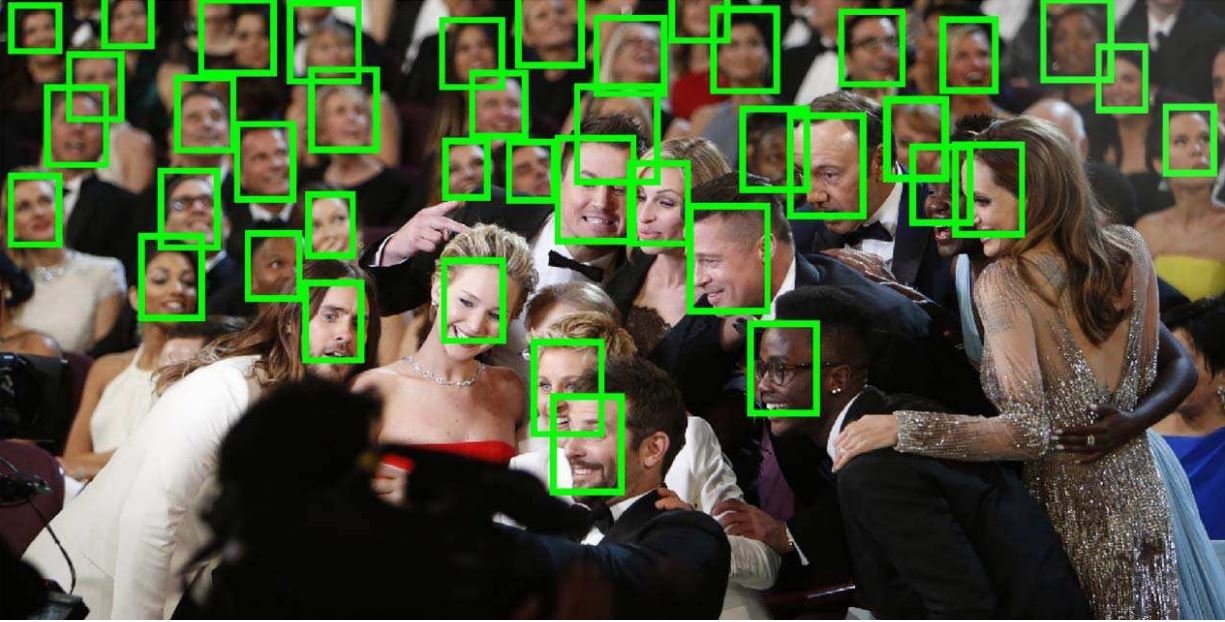
Most published research concentrates on the representation stage, because that is where novel architectures and loss functions live. Production accuracy, however, is usually decided upstream. A face that is never detected cannot be recognized, and a face that is detected but poorly aligned produces an embedding that sits in the wrong region of the vector space.
DeepFace handles all five stages by default, which is convenient but also easy to take for granted. Each stage is independently configurable, and the combinations behave differently. The library’s maintainers quantified this in a peer-reviewed benchmark of pipeline configurations, published in Bilişim Teknolojileri Dergisi, which tested recognition models against detectors, distance metrics, and alignment modes as a grid rather than in isolation.
How to Call DeepFace
Installation and import are deliberately minimal.
pip install deepfacefrom deepface import DeepFaceFace Verification
The verify function accepts two image paths and returns a dictionary. The key of interest is verified, a boolean indicating whether the pair belongs to the same person.
result = DeepFace.verify(img1_path = "img1.jpg", img2_path = "img2.jpg")Face Recognition and Vector Search
The find function searches a directory-based datastore and caches embeddings on disk. For larger deployments, DeepFace also supports explicit registration and querying against a vector database, with approximate nearest neighbor search available for scale.
DeepFace.register(img = "img1.jpg")
dfs = DeepFace.search(img = "target.jpg", search_method = "ann")
Supported backends include PostgreSQL, pgvector, MongoDB, Neo4j, Pinecone, and Weaviate. This brings facial recognition into the same infrastructure pattern as semantic search, where identity matching becomes a vector similarity problem.
Facial Attribute Analysis
objs = DeepFace.analyze(img_path = "img4.jpg", actions = ['age', 'gender', 'race', 'emotion'])Per the library’s own documentation, the age model achieves a mean absolute error of roughly 4.65 years, while the gender model reports 97.44% accuracy, 96.29% precision, and 95.05% recall. Note that the older detectFace function has been replaced by extract_faces, a change that breaks tutorials written before 2024.
The Face Recognition Model Portfolio
DeepFace currently wraps eleven recognition models. All of them are convolutional neural networks or closely related architectures, and all of them do the same job: convert a prepared face crop into a vector.
models = [
    "VGG-Face", "Facenet", "Facenet512", "OpenFace", "DeepFace",
    "DeepID", "ArcFace", "Dlib", "SFace", "GhostFaceNet", "Buffalo_L",
]
A few are worth understanding individually. VGG Face, written as VGG-Face in code, adapts the Oxford VGG architecture to facial data and remains the library default. FaceNet, introduced by Google researchers, learns a mapping directly into a Euclidean space where distance corresponds to similarity, and the original paper reported 99.63% on Labeled Faces in the Wild using only 128 bytes per face. Facenet512 is the 512-dimensional variant and is consistently the strongest performer in DeepFace’s own testing.
OpenFace, from Carnegie Mellon, is lighter and more permissively licensed. ArcFace introduced an additive angular margin loss that sharpened class separation. Dlib comes from Davis King’s image recognition library rather than an academic group. SFace and GhostFaceNet target efficiency, making them relevant candidates when you are constrained by lightweight model requirements.
Face Detectors: From OpenCV to YOLO
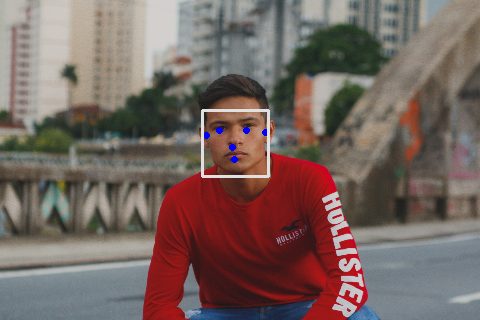
DeepFace wraps twenty detector backends, a substantial expansion from the five available a few years ago. They fall into rough tiers.
- Classical and fast: OpenCV uses a Haar cascade and requires frontal faces. SSD and Dlib are similarly quick, with Dlib using a histogram of oriented gradients approach.
- Landmark-aware: MTCNN and its faster variant return facial landmarks, which improves alignment quality. MediaPipe is optimized for mobile and edge deployment.
- High accuracy: RetinaFace performs best across the portfolio but is the most computationally expensive. YuNet and CenterFace offer a strong balance.
- Detection-model reuse: YOLOv8, YOLOv11, and YOLOv12 variants are available, letting teams reuse an object detection stack they already run.
Every DeepFace function accepts detector_backend and align arguments, so detection and alignment can be tuned independently of the recognition model.
backends = [
    'opencv', 'ssd', 'dlib', 'mtcnn', 'fastmtcnn', 'retinaface',
    'mediapipe', 'yolov8n', 'yolov11s', 'yolov12m', 'yunet', 'centerface',
]
Detector and model do not combine additively. The same recognition model can vary by several accuracy points depending on which detector feeds it, and the best pairing differs by model. For deeper background on this stage, see our overview of face detection.
What the Benchmarks Actually Show
This is where the received wisdom breaks down. Published papers report accuracy for a model evaluated under favorable, controlled conditions. DeepFace publishes something different: accuracy for complete pipelines, measured on Labeled Faces in the Wild across every combination of model, detector, distance metric, and alignment mode.
The two sets of numbers diverge sharply, and the gap is widest for the oldest models. Facebook’s original DeepFace network reported 97.35% in its 2014 paper but reaches only 69.0% as a component in this grid, because the published figure depended on a bespoke 3D alignment step that the generic pipeline does not reproduce. The table below shows the best result each model achieved anywhere in that grid.
| Model | Best pipeline accuracy (LFW) | Clears the 97.5% human line? |
|---|---|---|
| Facenet512 | 98.4% | Yes |
| FaceNet (128d) | 97.4% | Marginal |
| Dlib | 96.8% | No |
| VGG-Face | 96.7% | No |
| ArcFace | 96.7% | No |
| GhostFaceNet | 93.3% | No |
| SFace | 93.0% | No |
| OpenFace | 78.7% | No |
| DeepFace (Facebook) | 69.0% | No |
| DeepID | 66.5% | No |
Correction to a widely repeated claim: it is not accurate to say that VGG-Face, FaceNet, Dlib, and ArcFace have all surpassed human accuracy. Under DeepFace’s own reproducible pipeline benchmark, only Facenet512 clears the human line consistently, with FaceNet reaching it and the rest trailing below.
DeepFace’s documentation notes that human beings have 97.53% accuracy on this task, a figure that traces to the original Facebook DeepFace paper presented at CVPR 2014. Buffalo_L is a recent addition and does not yet appear in the published grid.
Why Detection and Alignment Do More Work Than Model Choice
The most useful finding in the benchmark grid is not which model wins. It is how much the preprocessing stages move the result.
DeepFace’s experiments indicate that detection improves recognition accuracy by up to 42%, while alignment adds up to 6%. The grid makes this concrete. ArcFace scores 96.6% when paired with RetinaFace and cosine distance, and 54.8% when detection is skipped and raw images are fed straight to the model. FaceNet drops from roughly 97% to 67.6% under the same conditions.
The practical implication is that detector selection deserves as much attention as model selection, and often more. A modest recognition model behind a strong detector will outperform a state-of-the-art model behind a weak one. This mirrors a pattern we see repeatedly in model performance work: the parts of the system nobody benchmarks are usually the parts that fail.
Alignment is close to free. It requires landmarks the detector already produces, and it is enabled by default.
Verification Embeddings and Vector Comparison at Scale
Once a face has been detected and aligned, the recognition model produces a verification embedding. Everything downstream operates on that vector rather than on pixels.
embedding_objs = DeepFace.represent(img_path = "img.jpg")DeepFace supports four distance metrics: cosine, Euclidean, L2-normalized Euclidean, and angular. Cosine is the default. The benchmark data shows no single metric dominating, though the choice interacts strongly with the model and detector pairing, which is why the grid is more informative than any single headline number.
Working with embeddings rather than images has architectural consequences worth planning for:
- Storage: a 512-dimensional float vector is far smaller than a face crop and can be indexed for approximate nearest neighbor retrieval.
- Privacy: embeddings are not reversible into the original image, but they remain biometric identifiers under most regulatory regimes. The project documentation recommends homomorphic encryption for embeddings held in untrusted environments.
- Portability: embeddings from different models are not interchangeable. Changing the recognition model invalidates every stored vector.
That last point is the one teams discover late. Model migration means re-enrolling the entire database, so the choice should be made before enrollment begins, not after. Our guidance on privacy-preserving deep learning and face blurring covers the handling requirements in more depth.
DeepFace as a Tool in Agentic Computer Vision
The most consequential recent change to DeepFace has little to do with accuracy. The project now ships a managed API built on top of the open-source library at deepface.dev, alongside a machine-readable agent surface.
That hosted service exposes one API for verification, embeddings, and vector comparison, with usage-based pricing and no GPU infrastructure to operate. More importantly for agentic computer vision, it publishes a Model Context Protocol endpoint at https://deepface.dev/mcp, accessed with a dedicated MCP key issued from the account dashboard.
An MCP endpoint turns face verification from a library you import into a tool an agent can call. The perception step stops being part of your application code and becomes an action available to a reasoning loop.
This is the pattern we expect to generalize. A vision language model can reason about a scene but cannot reliably verify an identity, because verification requires a purpose-built embedding space and a calibrated threshold. Wrapping a specialist model behind a callable interface lets the agent delegate that step, receive a confidence score, and continue reasoning. Classical recognition networks become perception primitives beneath a planning layer rather than the endpoint of a pipeline.
The design consideration is governance. An agent that can invoke facial recognition autonomously needs explicit constraints on when it may do so, which is an argument for keeping a human in the loop on any consequential identity decision.

Where DeepFace Fits in an Enterprise Vision Stack
DeepFace is a strong library and an incomplete system. It gives you recognition. It does not give you camera management, device orchestration, model versioning, access control, audit logging, or deployment across distributed sites.
For prototypes and single-application deployments, that gap is manageable. At enterprise scale, it becomes the entire problem. Teams that succeed with facial recognition typically spend a small fraction of their effort on the model and the majority on operations: keeping cameras calibrated, monitoring for drift, managing who can query what, and proving compliance.
Viso Suite exists to close that gap, providing the infrastructure layer around models like the ones DeepFace wraps, including deployment to edge AI hardware where video never leaves the site. Running inference locally is often the deciding factor for facial recognition workloads, since it removes the need to transmit biometric data across a network at all.
The evaluation question worth asking early is what happens after the prototype works. A notebook that verifies two images is a demonstration. A system that verifies thousands of identities per hour across dozens of sites, survives a model upgrade, and produces an audit trail a regulator will accept is a different engineering problem, and the library boundary is where that problem starts.
Limitations, Licensing, and Compliance
Three constraints deserve attention before deployment.
AI licensing is inherited. DeepFace itself is MIT licensed, but the wrapped models carry their own terms. VGG-Face, Dlib, ArcFace, and the YOLO detectors each come with separate license conditions that apply to your use. Commercial deployment requires checking each component you actually enable.
Demographic performance varies. Facial recognition accuracy is not uniform across skin tone, age, or gender presentation, and aggregate benchmark scores conceal that variation. Evaluating on a dataset representative of your actual population is a prerequisite, not an optimization.
Regulation is binding. Facial recognition is classified as high risk under the EU AI Act, with specific prohibitions on real-time remote biometric identification in public spaces. Similar rules exist in several US states. The technical question of whether you can deploy facial recognition is usually easier than the legal question of whether you may.
DeepFace also includes an anti-spoofing module, activated by setting anti_spoofing = True, which screens for presentation attacks using printed photos or screens. Any deployment where verification gates access should enable it.