As Artificial Intelligence (AI) models become more important and widespread in almost every sector, it is increasingly important for businesses to understand how these artificial intelligence models work and the potential implications of using them.
This guide will provide an overview of AI models and their various applications. We will explore popular use cases of AI models and discuss how they can be used effectively in business and other settings. In particular, we will cover the following:
Concepts of AI vs. ML vs. DL
What is an AI model, what’s an ML model, or a DL model?
Value of AI models for businesses
The most popular AI models
Subscribe to our newsletter
Stay connected with viso.ai and receive new blog posts straight to your inbox.
Almost every intelligent system in production today, from a warehouse camera that flags a near miss to a chatbot that drafts a supplier email, sits on top of an AI model.
AI learning models now span small statistical regression models that run on a laptop, foundation models trained on billions of texts, images, and video frames, and agentic systems that decide what to look at next. This guide covers the main types of AI models, how they are trained, and where they are heading.
AI vs. Machine Learning vs. Deep Learning
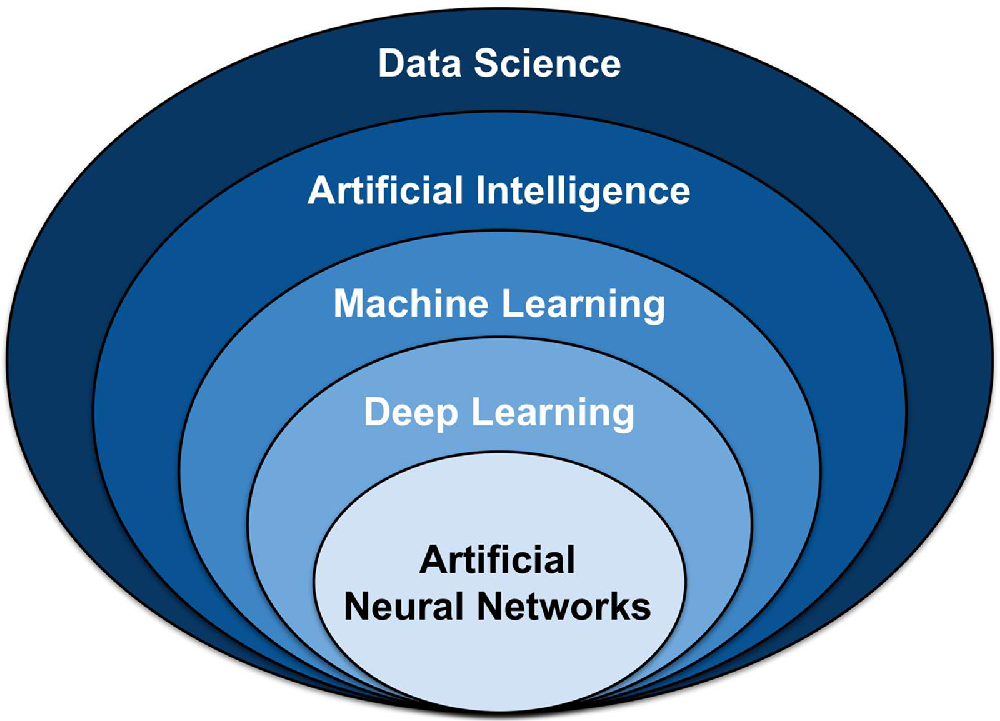
First, it is worth separating three terms that are still used interchangeably. Artificial intelligence, machine learning, and deep learning describe nested scopes rather than competing technologies, and the distinction matters when you are scoping a project or writing a procurement document.
Artificial Intelligence (AI) includes the sub-fields of Machine Learning (ML) and Deep Learning (DL).
Self-building AI vision
Bring a new AI vision application to life.
Turn ideas into real-world computer vision systems.
Artificial Intelligence (AI)
AI is the broad field within computer science concerned with building machines that perform tasks associated with human intelligence, including perception, reasoning, planning, and language. It includes methods that involve no learning at all, such as rule engines and search algorithms.
Machine Learning (ML)
Machine learning (ML) is the subset of AI in which a system improves at a task from exposure to data rather than from explicit instructions. Every ML model is an AI model, but the reverse is not true.
Within ML, the key distinction is how the model learns. Under supervised learning, an algorithm receives labelled training data and learns the mapping from input to ground truth. Unsupervised methods find structure in raw, unlabelled data, which suits tasks such as anomaly detection or fraud detection. Semi-supervised learning sits between the two and has become the practical default in computer vision, where labels are expensive and raw footage is abundant.
In computer vision, producing labelled training data is called image annotation. Modern pipelines increasingly use a pre-trained foundation model to propose masks or boxes, then route only the uncertain cases to a reviewer, a pattern known as human-in-the-loop labelling.
Deep Learning (DL)
Deep learning is the subset of ML built on artificial neural networks with many stacked layers. The architecture is loosely inspired by the human brain, in that simple interconnected units pass signals forward and adjust their connections during training. The analogy should not be pushed too far, because biological neurons and artificial ones behave very differently, but it explains the terminology.
Depth is what allows deep learning models to build a hierarchy of features on their own, moving from edges and textures to object parts and then whole objects, without a human specifying which features matter.
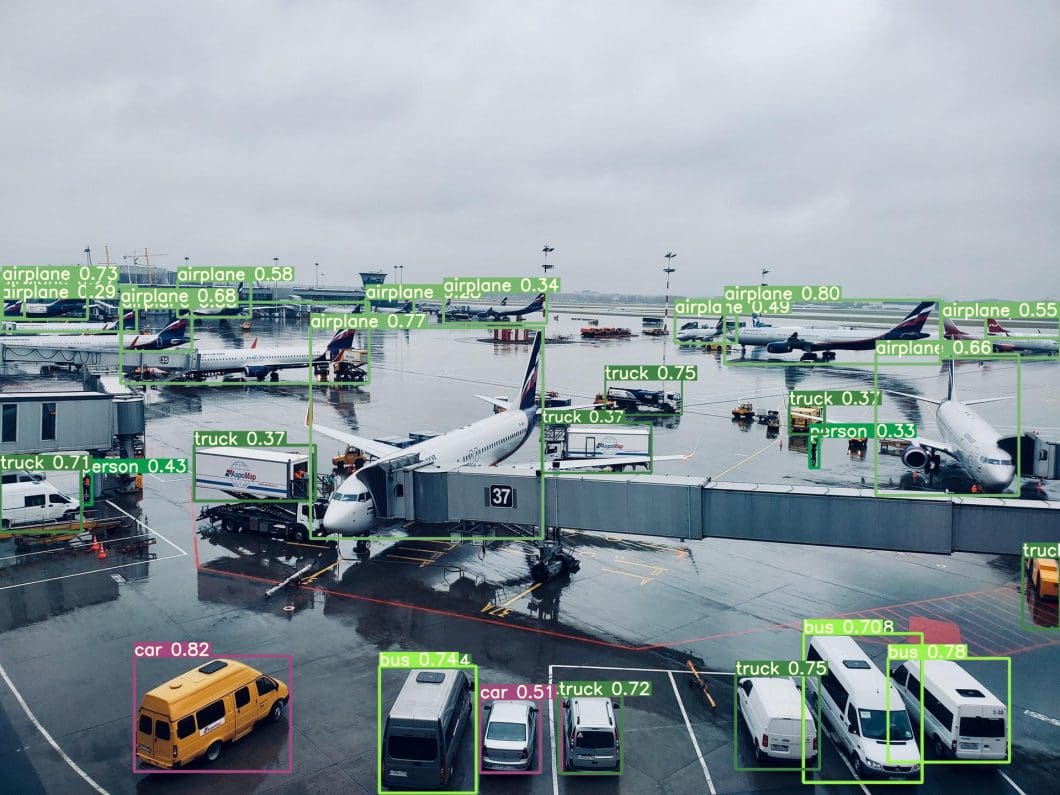
Aircraft and ground vehicle detection on an airport apron. Turnaround monitoring in aviation shows how a single detection model can feed both safety alerting and operational timing, built on Viso Suite.
What Is an AI Model?
An AI model is an algorithm plus the parameters it has learned from data, packaged so that it can turn a new input into a prediction. The parameters are the product of training and are what distinguishes a model from ordinary software: nobody wrote the decision rules by hand.
That property makes AI models well suited to problems where the rules are tacit, such as recognising a pattern in a noisy image or judging whether a worker is standing in a hazardous zone. It also makes them fallible in ways conventional software is not, which is why model performance monitoring belongs in the deployment plan from day one.
Barn owl or apple? Image recognition tasks can be equally challenging for AI models and humans. Source: @teenybiscuit
The Main Types of AI Models
Most working systems fall into one of five families. The table below is a rough guide to which family fits which problem.
Deep Learning Models Behind Modern Computer Vision
Convolutional Neural Networks (CNNs)
Convolutional neural networks (CNNs) apply learned filters across an image so that a feature detected in one corner is recognised anywhere in the frame. That property, called translation invariance, is why CNNs dominated vision for a decade and why they remain the backbone of choice for real-time edge inference, where ResNet and MobileNet variants are still hard to beat on cost per stream.
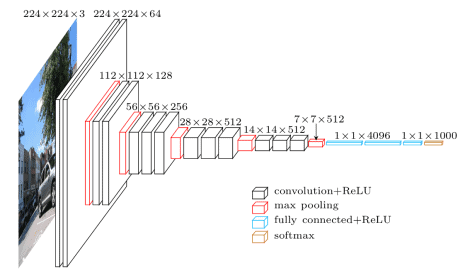
VGG Deep Convolutional Neural Network Architecture
Transformers and Vision Transformers
Transformers replaced convolution with attention, letting every part of an input attend to every other part. Vision transformers (ViT) brought that idea to images and now underpin most large vision backbones. In practice, hybrid designs that combine convolutional stems with attention blocks have won out for detection, because they keep transformer accuracy while remaining exportable to constrained hardware.
Vision-Language and Multimodal Models
Vision-language models (VLMs) are trained on paired texts, images, and increasingly video, which lets them accept a written prompt instead of a fixed class list. This is the shift that makes it possible to ask a camera network a question in plain language rather than build a bespoke detector for every new requirement.
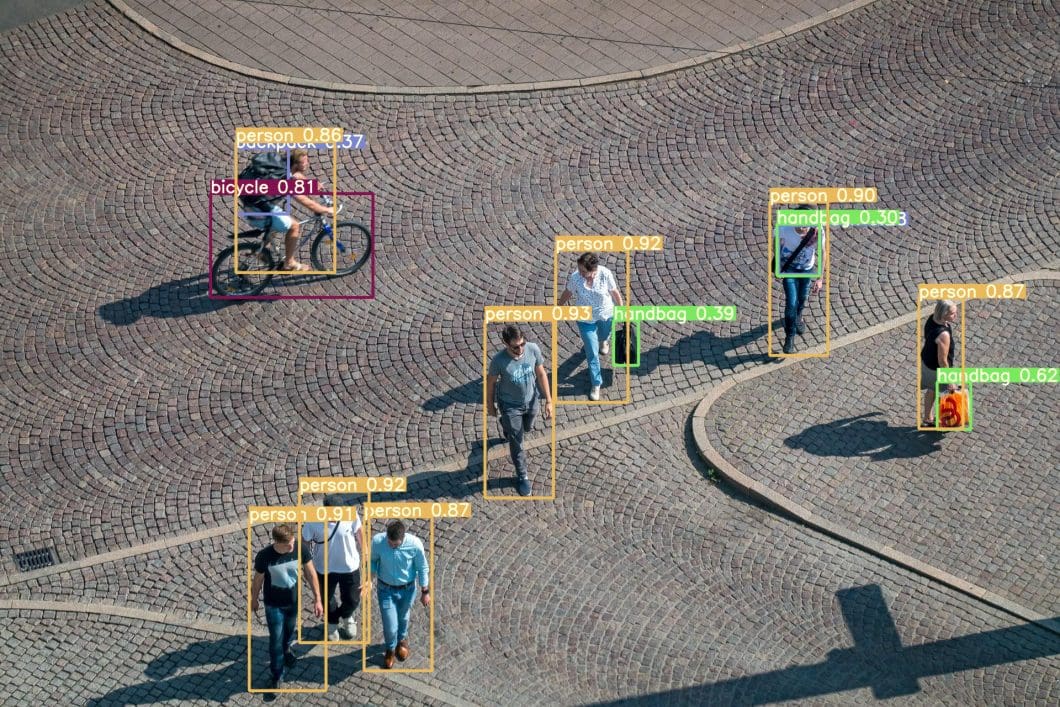
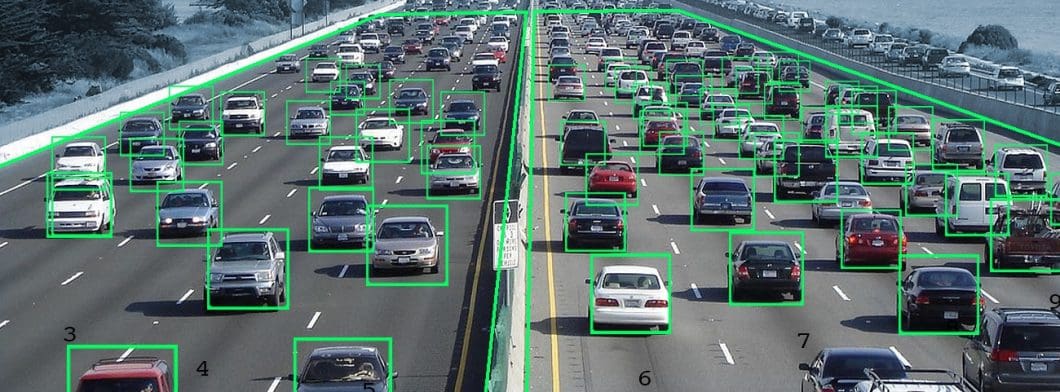
Multi-class detection across a dense urban scene, trained on the MS COCO dataset. Scenes like this one stress-test small-object accuracy, the same weakness that limits detection models on cluttered plant floors.
Classical Machine Learning Models That Still Matter
Deep learning absorbed most of the attention, but a large share of production AI still runs on classical algorithms. They train in seconds, need far less training data, and produce decisions you can explain to an auditor. Any team building a business case for computer vision will usually pair a vision model with one of these for downstream scoring.
Linear regression: predicts a continuous value from one or more inputs. Still the workhorse of forecasting in banking, retail, and construction.
Logistic regression: the standard method for binary classification, closely related to linear regression but bounded to a probability.
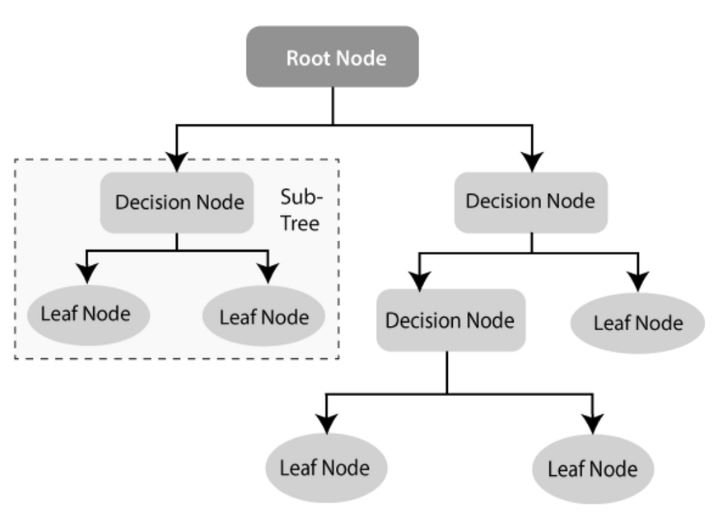
Decision tree: splits data into progressively smaller branches to reach a conclusion, and remains one of the most readable of all AI models.
Random forest: an ensemble learning method that averages many decision trees to cut variance and improve accuracy.
Support vector machines: effective on small, high-dimensional datasets, especially in text classification.
Naive Bayes: a probabilistic classifier that assumes feature independence, fast and surprisingly durable for filtering tasks.
K-nearest neighbours: classifies by proximity to known examples, simple but slow as data volume grows.
Linear discriminant analysis and learning vector quantization: older multi-class methods that still appear in medical and industrial classification work.
Decision Tree StructureLinear regression for machine learning
Reinforcement Learning and Learning by Trial and Error
Reinforcement learning takes a different route. Instead of labelled examples, an agent acts in an environment and receives a reward or penalty, so the policy improves through trial and error. It is the natural fit for control problems: robot navigation, energy scheduling, and process tuning where the correct action depends on a sequence of earlier ones.
Two developments have made it more relevant to vision teams. First, deep reinforcement learning uses a neural network as the policy, so the agent can act directly on pixels. Second, reinforcement learning from feedback became the standard method for aligning large language and vision-language models, which means most people using a chat assistant are already using it indirectly.
The Most Important AI Models in 2026
YOLO26
The YOLO family remains the reference point for real-time object detection. Recent YOLO releases shifted the emphasis from raw accuracy on benchmark datasets to deployability, and YOLO26, released by Ultralytics in January 2026, is the clearest example. It removes non-maximum suppression from inference so the model is end-to-end, drops distribution focal loss, and adds training changes aimed at small objects, which is the failure mode that matters most on cluttered industrial sites.
One architecture now covers detection, instance and semantic segmentation, classification, pose estimation, and oriented bounding boxes across five model sizes.
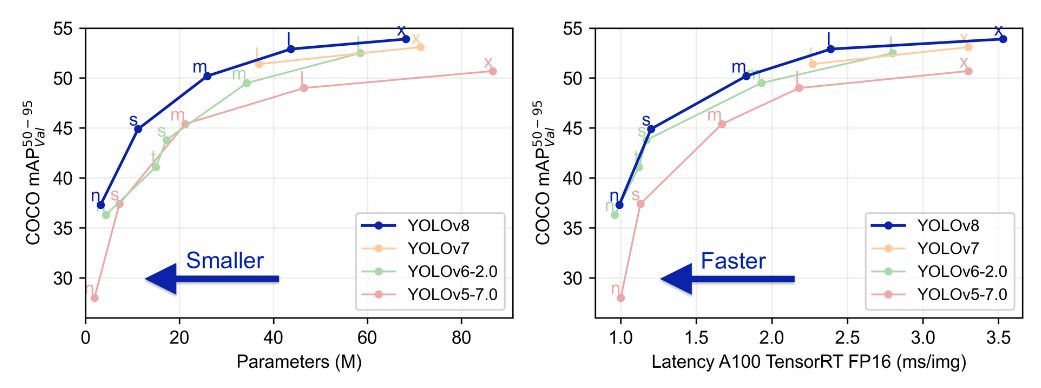
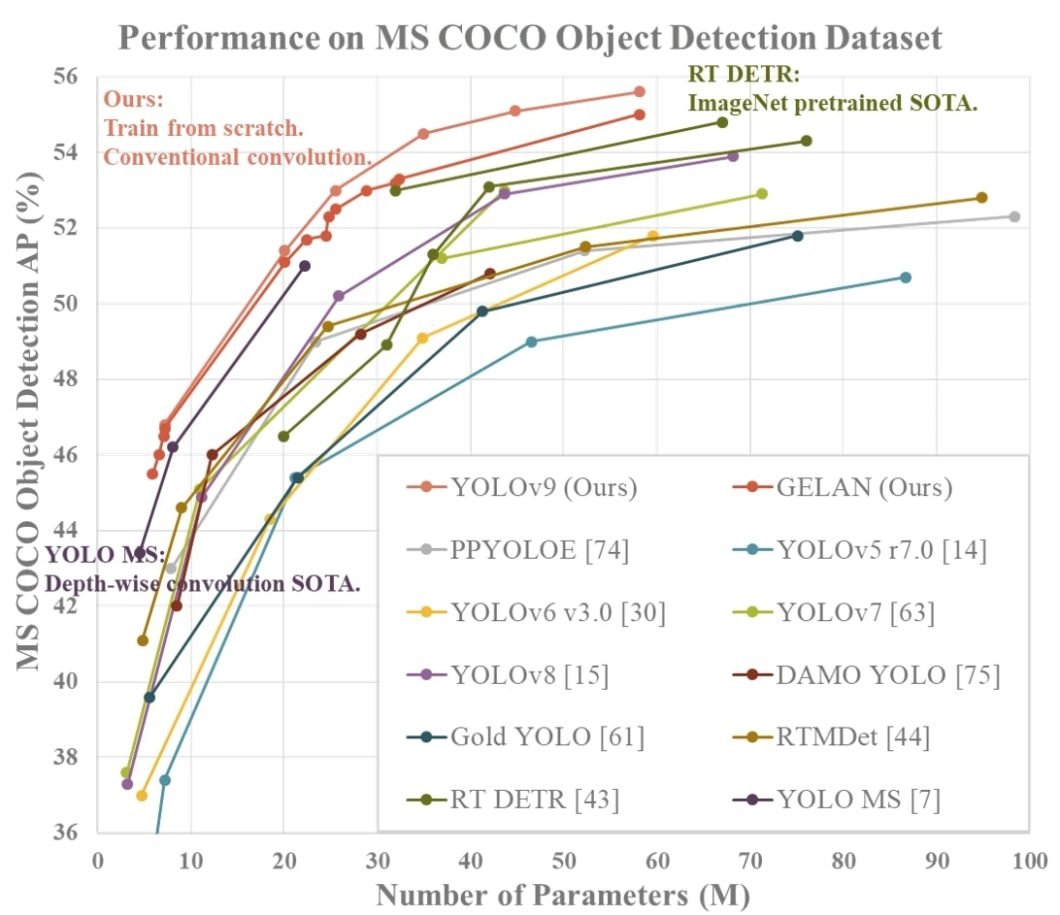
Accuracy against latency for successive YOLO generations. Each release pushes the frontier outward, which in practice means more camera streams per edge device at the same detection quality.Comparison of YOLO AI models on the COCO dataset. Source
Segment Anything 3
Meta released SAM 3 in November 2025, and it changes what segmentation means in a production pipeline. The original Segment Anything paper introduced promptable segmentation from clicks and boxes. SAM 3 accepts a short noun phrase or an image exemplar and returns masks and stable IDs for every matching instance in an image or video, a capability Meta calls promptable concept segmentation. The accompanying release notes and SA-Co benchmark cover the evaluation set.
For industrial teams, the significance is practical. Asking for “shipping container” or “spilled liquid” without training a dedicated model collapses the gap between identifying a new hazard and monitoring it.
AI Model Segment Anything Architecture
Open-Weight Language Models
On the language side, the open-weight tier has closed much of the distance to closed APIs. Mistral Large 3, released in December 2025, uses a sparse mixture-of-experts design in which only a fraction of its parameters activate for any given token, which keeps inference cost far below what the total parameter count suggests.
Sparse routing, long context windows, and downloadable weights are now the baseline expectation rather than a differentiator, and they matter for vision teams because large language models are what turn detections into a queryable, self-hostable interface.
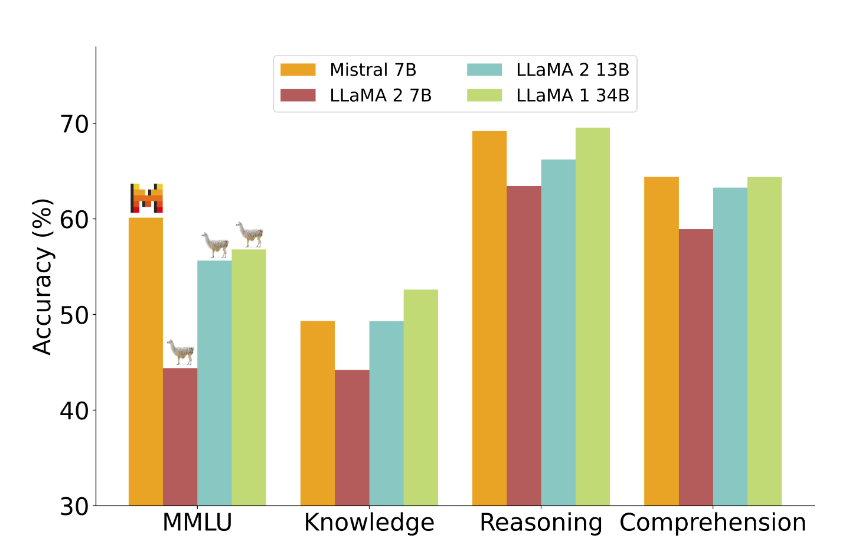
Benchmark comparison of a Mistral model across task categories. Source: official paper
From Single Models to Agentic Computer Vision
The most consequential change is architectural rather than algorithmic. A conventional deployment runs one model per question: a PPE detector, a forklift detector, a queue counter. Agentic computer vision instead composes perception models, memory, and tools under a planner that decides which model to invoke and when.
The distinction is between a system that answers a question you specified in advance and one you can ask a question you had not anticipated. That is the practical threshold between visual perception and visual general intelligence.
This is also where physical AI converges with vision. Once a camera estate becomes queryable, the same infrastructure supports investigation, trend analysis, and closed-loop response.
Video analytics tracking vehicles across a yard. In logistics settings, the same vehicle detection stream supports throughput measurement and pedestrian separation at once.
Training Models and Running Them in the Real World
Training models is now the easy part. Frameworks such as PyTorch and TensorFlow reduce a training run to a few lines, and most teams start from pre-trained weights rather than random initialisation. What defeats projects is everything after that: versioning, device fleets, drift, and the cost of inference at scale. This is the main reason computer vision projects fail to move past the proof-of-concept stage.
Hardware choice follows the deployment target. GPUs and accelerators such as NVIDIA Jetson handle training and heavier inference, while CPUs and coprocessors including Intel VPU and Google Coral TPU cover constrained sites. Running models at the network edge through edge AI keeps video local, which lowers bandwidth cost and simplifies privacy compliance.
Four patterns describe most of the value businesses extract from AI models:
Collect proprietary data.Data collection from cameras and sensors builds an asset competitors cannot buy.
Instance segmentation performed with Meta’s computer vision framework, Detectron2
What Comes Next for AI Models
The direction of travel is toward fewer, more general models doing more work, prompted rather than retrained, and increasingly coordinated by an agent that decides what to look at. Understanding the types of AI models available, and which constraint each one relieves, is what separates a working deployment from a stalled pilot. Our overview of computer vision trends covers where this is heading next.
Build, deploy, and scale AI models with our end-to-end platform, Viso Suite. You can read the whitepaper here, or continue with these related guides:
Classical machine learning models, deep learning models, reinforcement learning agents, foundation models, and agentic systems that orchestrate several models together.
No. Every ML model is an AI model, but AI also includes systems that follow hand-written rules and never learn from training data.
It depends on the constraint. Real-time detection on edge hardware favours a compact YOLO-family model, open-vocabulary segmentation favours SAM 3, and flexible querying favours a vision-language model. Many production systems combine all three.
A pre-trained model has learned general features from a large public dataset. Fine-tuning continues that training on your own data so the model adapts to your cameras, lighting, and object classes.
Classical regression models can work with hundreds of rows. Training a vision model from scratch takes hundreds of thousands of images, but fine-tuning a pre-trained backbone often needs only a few hundred well-annotated examples per class.
On this page
On this page
Build real-world AI systems
Skip months of data, training, and coding. Build your AI vision system in an hour.