

ImageNet is the annotated image database that moved computer vision from a research curiosity to a deployable technology. Assembled at Princeton University in the late 2000s, it holds more than 14 million labeled photographs organized by a semantic hierarchy borrowed from linguistics. The competition built on top of it ran for eight years and produced the model architectures that most production vision systems still descend from.
This guide covers what the ImageNet dataset actually contains, how it was assembled, what its benchmark measured, and why it continues to shape machine learning practice more than fifteen years after the first release. It also sets out the dataset’s documented limitations, which matter to anyone deploying vision models outside a benchmark environment.
What Is the ImageNet Dataset?
ImageNet is a publicly available large-scale image database of annotated photographs, structured according to the WordNet lexical hierarchy. Every concept in WordNet is described by a synonym set, or synset, and ImageNet populates those synsets with verified, full-resolution photographs. The result is a labeled corpus in which each category sits at a known position in a tree of meaning rather than in a flat list.
The scale is easier to grasp as a set of figures:
- 14,197,122 images indexed across the ImageNet database.
- 21,841 synsets populated, averaging roughly 650 manually verified images each.
- 1,034,908 images annotated with object bounding boxes.
- 1,000 synsets supplied with scale-invariant feature transform (SIFT) features, covering about 1.2 million images.
One detail is frequently misunderstood. ImageNet does not own the photographs it indexes. It distributes URLs, thumbnails, and the annotation layer, while copyright remains with the original photographers. That structure is why access has always been governed by a research-use agreement rather than an open media license, and it explains why the project’s real intellectual contribution is the labeling, not the imagery.
Bring a new AI vision application to life.
How Fei-Fei Li and the ImageNet Team Built a Large-Scale Image Database
The project began with an argument about priorities. In the mid-2000s, most of the field was refining algorithms against small datasets such as Caltech 101 and PASCAL VOC. Fei-Fei Li took the opposing position: that the binding constraint was data, and that a sufficiently large and well-organized corpus would change what models could learn.
Working at Princeton University, Li connected with WordNet researcher Christiane Fellbaum and adopted the WordNet noun hierarchy as the organizing backbone. The bottleneck then became annotation. Verifying tens of millions of candidate images through undergraduate labor would have taken an estimated nineteen years.
Amazon Mechanical Turk Changed the Arithmetic
Crowdsourcing solved the throughput problem. By distributing verification tasks through Amazon Mechanical Turk, the ImageNet team recruited roughly 49,000 workers across 167 countries. Rather than asking workers to generate labels, the design asked them a narrower, more reliable question: Does this image contain the given concept? Multiple independent votes per image-concept pair, with confidence thresholds that varied by category difficulty, provided the quality control.
The first public result, presented at CVPR 2009, covered 12 subtrees, 5,247 synsets, and about 3.2 million images. The reception was muted. The conference accepted the work as a poster rather than an oral presentation, and reviewers questioned why anyone would attempt thousands of categories when single-object recognition remained unsolved.
The ImageNet bet was that data would redefine how the field thought about models. Three years after the paper landed to little interest, the benchmark it enabled ended the era of hand-engineered visual features.
You can read the original description of the construction methodology in the CVPR 2009 paper, which remains the clearest account of how the hierarchy and the image annotation pipeline were designed.
Inside the ImageNet Large Scale Visual Recognition Challenge
The dataset alone would not have reorganized the field. What did was the benchmark layered on top of it. The ImageNet Large Scale Visual Recognition Challenge (ILSVRC) ran annually from 2010 to 2017 and gave researchers a fixed target, a hidden test set, and a public leaderboard.
ILSVRC used a curated subset rather than the full ImageNet corpus. The classification and localization task covered 1,000 object categories and contained 1,281,167 training images, 50,000 validation images, and 100,000 test images. Training data came from ImageNet proper, while validation and test images were collected separately from Flickr and search engines specifically so that no competitor could have seen them during development.
That distinction matters. The subset is commonly called ImageNet-1k, and it is what most people mean when they say a model was “trained on ImageNet.” The full ImageNet database, sometimes labeled ImageNet-21k, is roughly ten times larger and used far less often.
The challenge expanded its scope over time:
- Image classification, present from the first challenge in 2010, scoring whether a model named the correct object.
- Single-object localization, added in 2011, requires a bounding box alongside the label.
- Object detection, added in 2013, requires every instance of every target class to be found.
Scoring used two metrics that are still standard in model performance reporting. Top-1 error counts a prediction wrong unless the highest-confidence label matches the ground truth. Top-5 error is more forgiving, counting a prediction correct if the true label appears anywhere in the model’s five most confident guesses. Nearly all historical ILSVRC comparisons cite top-5.
The ILSVRC Results That Reset Computer Vision
The year-by-year winning scores tell the story of the field’s transition from feature engineering to deep learning.
| Year | Winning entry | Top-5 error | Approach |
|---|---|---|---|
| 2010 | NEC-UIUC | 28.2% | SIFT and LBP features with SVM classifiers |
| 2011 | XRCE | 25.8% | Compressed Fisher vectors |
| 2012 | SuperVision (AlexNet) | 15.3% | GPU-trained convolutional neural network |
| 2013 | Clarifai | 11.7% | Deconvolution-tuned CNN |
| 2014 | GoogLeNet | 6.7% | Inception modules, 22 layers |
| 2015 | ResNet | 3.6% | Residual connections, 152 layers |
| 2016 | CUImage | 3.0% | Ensemble methods |
| 2017 | SENet | 2.3% | Squeeze-and-excitation blocks |
The 2012 result is the inflection point. AlexNet finished at 15.3% top-5 error, or 16.4% using only the provided training data, while the best non-neural entry scored 26.2%. That margin was too large to dismiss as tuning. Every subsequent winner used convolutional neural networks.
A common error worth correcting: sub-5% top-5 error was not reached in 2013. The 2013 winner scored 11.7%. The 5% threshold, which approximates trained human performance on this task, was first crossed in 2015 by ResNet at 3.6%.
The 2014 challenge is worth noting separately because it produced two lasting architectures. GoogLeNet won classification, while the runner-up VGG became the more widely reused backbone despite placing second. Full results for every year are published on the official ILSVRC archive.

Why ImageNet Still Matters for Deep Learning and Machine Learning
The competition ended in 2017, but the dataset’s influence grew afterward. Its second life is as a pretraining corpus, and this is the mechanism by which ImageNet touches nearly every applied vision project.
A model trained on 1.2 million labeled photographs learns general visual structure: edges, textures, part configurations, and object-level regularities. Those learned features are not specific to the 1,000 ILSVRC classes. They can be repurposed, which is the basis of transfer learning.
The practical workflow is consistent across industries:
- Start from a backbone whose weights were learned on ImageNet-1k or ImageNet-21k.
- Replace the final classification layer with one sized to the target problem, often just a handful of classes.
- Fine-tune on a domain dataset that may contain only a few thousand annotated examples.
- Monitor for overfitting, which becomes the dominant risk once the target dataset is small relative to model capacity.
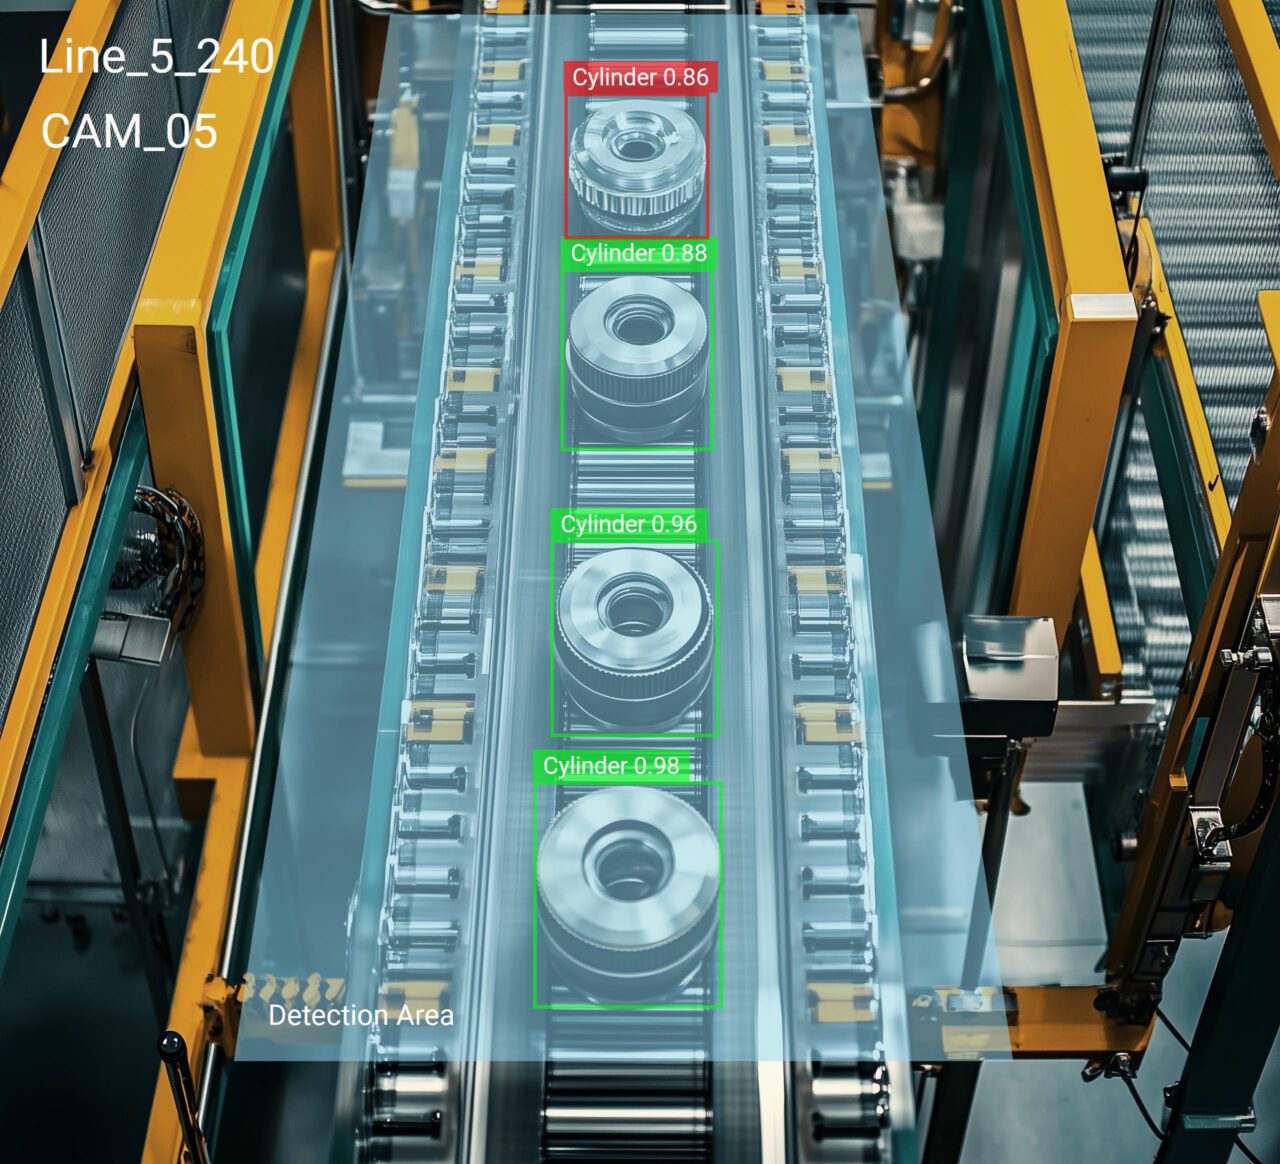
This is why a defect detector trained on a few thousand factory photographs can reach usable accuracy at all. It is not learning vision from scratch. It is inheriting fifteen years of accumulated visual statistics and adapting the last layers. The same logic underpins vision transformers, which are typically pretrained on ImageNet-21k before fine-tuning on smaller benchmarks.

ImageNet and the Shift Toward Agentic Computer Vision
Benchmarks shape research agendas, and ImageNet’s framing of vision as single-label classification defined the field’s ambitions for close to a decade. That framing has now been superseded. Contemporary systems are expected to describe scenes, answer questions about them, and take action on the results.
Agentic computer vision describes systems that plan and act over visual input rather than emitting a label per frame. These systems still depend on the perception layer that ImageNet pretraining produces. Vision language models and large vision models handle reasoning and instruction-following, while fast, cheap, ImageNet-derived backbones handle detection and tracking underneath them.
This division of labor has real operational consequences. Running a large multimodal model on every frame of every camera is prohibitively expensive. A conventional detector filters the stream, and the reasoning layer engages only on events that warrant it. Platforms such as Viso Suite are built around exactly this layering, combining lightweight models at the edge with higher-level analysis where it earns its cost.
Meanwhile, the foundation model paradigm has partly displaced supervised ImageNet pretraining. Self-supervised methods train on far larger unlabeled image collections and often outperform ImageNet-supervised features. ImageNet’s role has shifted accordingly, from primary training corpus toward standardized evaluation set, a function it still performs across most published computer vision tasks.
Known Limits of the ImageNet Database
Treating benchmark accuracy as a proxy for real-world reliability is the most common mistake made with this dataset. Several documented limitations explain why.
The person subtree. The full ImageNet contained 2,832 categories under the person node, many derived from WordNet nouns that are offensive, unverifiable from a photograph, or both. A 2020 audit by the ImageNet team concluded that at most 158 of those synsets should remain, and only 139 held enough data to be usable. The 2021 Winter release reduced the corpus from 21,841 concepts to 19,167, removing the problematic categories. ILSVRC-1k was largely unaffected, since it includes only three person categories.
Distribution mismatch. ImageNet photographs are web images: well-lit, centered, and usually taken by someone who intended to photograph the subject. Industrial camera feeds are none of those things. A model at 95% ImageNet accuracy can degrade sharply under motion blur, glare, unusual viewing angles, or partial occlusion.
Label granularity. More than 100 of the 1,000 ILSVRC classes are dog breeds, a legacy of WordNet’s uneven depth. The benchmark therefore rewards fine-grained distinctions in one narrow domain while treating entire categories of industrially relevant objects as single classes.
Annotation noise. Later re-audits found meaningful label error rates in the validation set, which places a practical ceiling on how much of a reported accuracy gain represents genuine capability. The methodology behind the benchmark, including its known error sources, is documented at length in the ILSVRC retrospective paper.
For teams choosing an evaluation set, it is worth comparing against COCO and PASCAL VOC, which were designed around multi-object scenes rather than single-label image classification.

Further Reading
To go deeper on the architectures and concepts referenced here, these guides are a useful next step:
- ResNet: how residual connections made very deep networks trainable.
- What Is Computer Vision: a foundational overview of the field.
- Top AI Influencers: profiles of the researchers behind these advances.
- Deep Learning vs Machine Learning: where the two disciplines diverge.
