

VGG, sometimes referred to as VGGNet, is one of the most recognizable convolutional neural network architectures in the history of computer vision. Released in 2014 by researchers at the University of Oxford, the VGG model showed that depth, applied through a stack of very small convolutional filters, was the single most effective lever for improving accuracy on large-scale image recognition benchmarks.
More than a decade later, the architecture remains a fixture in production pipelines, research baselines, and university curricula. This guide explains how the VGG architecture works layer by layer, why its design choices mattered, where it falls short against newer networks, and how classical backbones still contribute to agentic computer vision systems today.
What Is the VGG Model?
VGG stands for Visual Geometry Group, the research lab at the University of Oxford where the architecture was developed. It is a deep convolutional neural network built from a uniform stack of layers, and unlike the CNN architectures that preceded it, VGG holds filter size constant and varies only depth. Karen Simonyan and Andrew Zisserman introduced it in the paper “Very Deep Convolutional Networks for Large-Scale Image Recognition.”
The word “deep” in that title refers to the number of layers that carry learnable parameters. VGG16 and VGG19, the two configurations the Visual Geometry Group publicly released, contain 16 and 19 weight layers, respectively. Both are still among the most widely cited image recognition architectures ever published, and both are still shipped as pretrained models in every major deep learning framework.
VGG’s contribution was not a novel building block. It was the systematic proof that stacking many small 3×3 convolutional filters beats a shallower network built from larger receptive fields.
Bring a new AI vision application to life.
What Is VGG16?
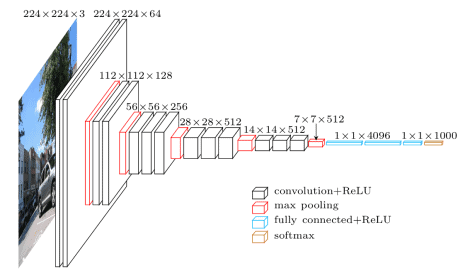
VGG16 is the 16-layer configuration of the VGG model. It combines 13 convolutional layers with three fully connected layers, giving 16 weight layers in total, and it carries roughly 138 million parameters.
The network takes a fixed 224×224 input image and classifies it into 1,000 ImageNet categories, from keyboards and pencils to hundreds of animal species. It reaches approximately 92.7% top-5 accuracy on ImageNet, a dataset of more than 14 million labeled images. Its central improvement over AlexNet was replacing large kernels with sequences of 3×3 filters. Training took several weeks on Nvidia Titan Black GPUs.
What Is VGG19?
VGG19 follows the same design philosophy with three additional convolutional layers. It holds 16 convolutional layers and three fully connected layers, for 19 weight layers and roughly 144 million parameters.
One point causes persistent confusion in secondary sources.
VGG19 is frequently described as having 19 convolutional layers, and VGG16 as having 16. Neither is accurate. The number refers to weight layers in total, so VGG19 contains 16 convolutional layers plus three fully connected layers, and VGG16 contains 13 plus three.
The extra depth in VGG19 buys a marginal accuracy gain over VGG16 at meaningfully higher compute and memory cost, which is why VGG16 remains the more common choice in practice.
Inside the VGG Architecture
Every VGG configuration is built from the same repeating pattern: a run of convolutional layers, then a downsampling step, repeated five times, followed by a classifier head. That regularity is the reason the VGG architecture is so often used to teach convolution operations.
- Input: The network expects a 224×224 RGB input image. For the ImageNet competition, the authors cropped the center 224×224 patch from each image to keep input dimensions consistent.
- Convolutional layers: All convolutional filters use a 3×3 receptive field, the smallest size that still captures up, down, left, and right. Stride is fixed at one pixel and padding at one pixel, so spatial resolution survives each convolution intact. Some configurations also add 1×1 filters that act as a linear transformation of the input channels.
- Activation: Every hidden layer uses ReLU, the rectified linear unit, which passes positive values through unchanged and outputs zero otherwise. VGG deliberately omits Local Response Normalization, since it raises memory use and training time without improving accuracy.
- Pooling: Each max pooling layer uses a 2×2 window with a stride of two, halving height and width. There are five of them, and they are the only place where spatial dimensions shrink.
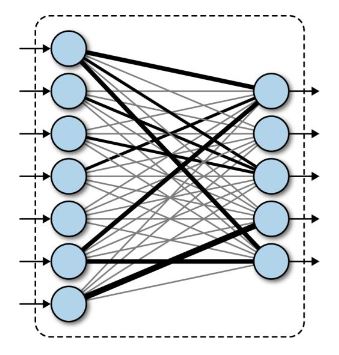
- Fully connected layers: Three fully connected layers close the network. The first two carry 4,096 channels each, and the third carries 1,000, one per class, followed by a softmax.
How the Number of Layers and Filters Scale
Width doubles as depth increases. The first block applies 64 filters, and that count doubles after every max pooling layer until it reaches 512 filters, which the final two blocks share. The effect is a trade: each feature map gets smaller spatially while becoming richer in channels, so the network exchanges resolution for semantic abstraction as data moves forward.
| Block | Convolutional Layers (VGG16) | Filters per Layer | Output Feature Map |
|---|---|---|---|
| 1 | 2 | 64 | 112 x 112 x 64 |
| 2 | 2 | 128 | 56 x 56 x 128 |
| 3 | 3 | 256 | 28 x 28 x 256 |
| 4 | 3 | 512 | 14 x 14 x 512 |
| 5 | 3 | 512 | 7 x 7 x 512 |
Output dimensions are measured after the max pooling layer that closes each block, starting from a 224×224 input image.
Why Small Convolutional Filters Work
Small convolutional filters appear to limit how much of an image any single layer can see. Depth compensates completely. Two stacked 3×3 layers cover the same 5×5 receptive field as a single larger kernel, and three stacked layers cover 7×7, so depth recovers whatever spatial reach the small filters appear to give up.
The parameter arithmetic explains the rest. Three 3×3 layers operating on C channels require 27C² weights, while one 7×7 layer covering the same field requires 49C². VGG therefore gets a wider effective receptive field, roughly 45% fewer parameters in that comparison, and two additional ReLU non-linearities that make the learned decision function more discriminative.
Depth was the variable that mattered. By holding filter size constant at 3×3 and varying only the number of layers, the Oxford team isolated depth as the driver of accuracy and set the direction for the next several years of deep learning research.
How VGG Performed on ImageNet
VGG entered the 2014 ImageNet Large Scale Visual Recognition Challenge and finished with results that reshaped expectations for network depth.
- Localization: VGG won the task outright, posting a localization error of roughly 25.3% and taking the top four positions on the leaderboard.
- Classification: VGG placed second with a 7.3% top-5 error, behind GoogLeNet at 6.7%.
- Single-model comparison: A single VGG network reached about 7.0% top-5 error, ahead of a single GoogLeNet by roughly 0.9 percentage points. GoogLeNet’s overall win came largely from ensembling.
- Prior years: Both figures decisively beat the 2013 winner, Clarifai, which recorded 11.7% without external training data.
Full per-entry results are published in the official ILSVRC-2014 leaderboard, and the released weights are still distributed by the Visual Geometry Group at Oxford. The ILSVRC-2014 localization win showed that one deep convolutional neural network could support classification and spatial localization from the same feature hierarchy.

Complexity and Limitations of the VGG Model
Uniformity made VGG easy to understand and expensive to run. The costs are concentrated in the fully connected layers, where a single 7x7x512 feature map flattens into 25,088 values feeding a 4,096-unit layer.
- Parameter count: Roughly 138 million weights for VGG16 and 144 million for VGG19, the large majority of them in the classifier head rather than the convolutional stack.
- Storage: The pretrained VGG16 weight file exceeds 500 MB, which complicates deployment to constrained hardware.
- Training cost: Weeks of multi-GPU training for the original ImageNet run, and slow fine-tuning even today.
- Inference latency: High FLOP counts per image make VGG a poor fit for real-time edge computing workloads.
For teams that need accuracy per watt, MobileNet, EfficientNet, and other lightweight computer vision models are usually the better answer.
VGG Versus ResNet and Modern Backbones
Depth improves the class of functions a deep convolutional neural network can fit, which raises an obvious question: why not VGG50, or VGG100? The answer is the vanishing gradient problem.
Backpropagation updates each weight by a step proportional to the gradient of the loss, computed through the chain rule. As that gradient propagates backward through many layers, it is multiplied by a long series of local gradients, and the product shrinks toward zero. Updates to the earliest layers become vanishingly small, training stalls, and adding layers stops helping. This is specific to very deep networks and should not be confused with the behavior of a shallow artificial neural network.
ResNet resolved this with skip connections, which insert an identity path around each block so the local gradient is one. Gradients flow backward undisturbed, and depths of 50, 101, or 152 layers become trainable. ResNets are also less parameter-heavy than VGG at comparable accuracy. Vision Transformers later moved past convolution entirely for many tasks, and detection families such as YOLO dominate real-time deployment.
Where VGG Still Matters in Computer Vision
VGG is no longer a competitive classifier, and yet it has not disappeared. Its ordered, predictable layer stack makes it unusually well suited to jobs that have nothing to do with winning benchmarks.
- Feature extraction: Intermediate VGG activations remain a dependable general-purpose descriptor. Truncating the network and reading a mid-level feature map is a standard feature extraction technique.
- Transfer learning: Freezing the convolutional stack and retraining only the classifier is a fast, well-documented path for small custom datasets, and VGG is a common starting point for transfer learning.
- Perceptual loss: Style transfer, super-resolution, and image generation pipelines routinely compare VGG feature maps rather than raw pixels, because distances in VGG feature space align better with human judgments of similarity.
- Baselines and teaching: When a paper needs a control, or a course needs an architecture students can trace by hand, VGG is the reference point.
VGG and Agentic Computer Vision
The frontier has moved well past classification accuracy. Agentic computer vision now sets the agenda, placing perception models inside a loop that reasons about what it sees, decides what to look at next, and acts without a human issuing each instruction.
Classical backbones occupy a specific and durable place in that stack. An agentic system needs cheap, reliable perception primitives it can call thousands of times: an embedding to compare two frames, a feature map to seed a tracker, a confidence score to decide whether escalation to a heavier model is warranted. VGG-style feature extraction fills exactly that role, particularly where deterministic, auditable behavior matters more than peak accuracy.
Above those primitives sit the reasoning components. Vision language models and large vision models interpret scenes and choose actions, while lightweight CNNs handle the high-frequency work that would be wasteful to route through a foundation model. The result is a tiered architecture rather than a single network.
Understanding VGG is still worth the effort. It forced four questions into the open: how depth, receptive field, parameter count, and inference cost trade against one another. Those are precisely the questions that govern how agentic computer vision systems get designed today.
Continue Learning About Deep Learning and Computer Vision
Explore related architectures and applied computer vision topics:
- Image Classification: How Models Assign Labels to an Input Image
- Model Performance: Metrics That Matter Beyond Top-5 Accuracy
- Physical AI: Where Perception Meets Action in the Real World
- TensorFlow Lite: Real-Time Computer Vision on Edge Devices
- Edge Intelligence: Deep Learning and Edge Computing
- Automatic Number Plate Recognition: Building Real-World Computer Vision Apps
- OpenPose: An Open-Source Model for Pose Estimation