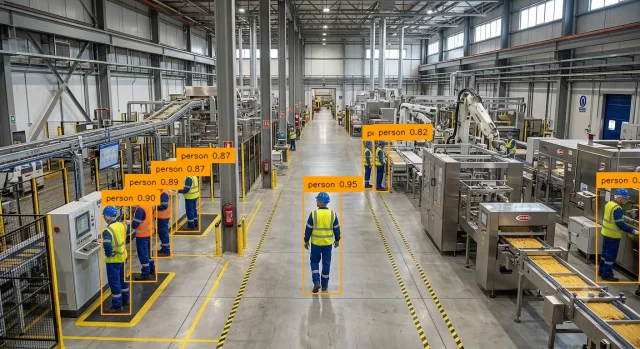
Convolutional neural networks sit underneath most of the computer vision systems running in production today, from weld inspection on an automotive line to occupancy analysis in a distribution center. Understanding how a CNN moves from raw pixels to a decision clarifies both what these models do well and where they need help. This guide walks through CNN architecture layer by layer, traces how the field arrived at current designs, and examines how CNNs now operate as components inside larger agentic computer vision systems rather than as standalone classifiers.
What Is a Convolutional Neural Network?
A convolutional neural network is a class of deep neural net built to process data with a grid-like topology, most commonly image data. Instead of treating every pixel as an independent measurement, a CNN assumes that neighboring pixels are related and that a useful pattern remains useful wherever it appears in the frame. That assumption is what separates CNNs from fully dense networks and what makes them tractable on realistic image classification workloads.
The mechanism behind that assumption is the convolution operation. A small matrix of learned weights, called a kernel or filter, slides across the input images and computes a weighted sum at every position.
The result is a feature map that records where a particular pattern was detected. Early filters typically respond to edges and color transitions. Deeper filters combine those responses into textures, then object parts, then whole objects.
Because the same kernel is reused across every spatial position, a CNN shares weights rather than learning a separate parameter for each pixel. This single design choice reduces the number of trainable weights by orders of magnitude compared with a dense network of equivalent capacity.
That weight sharing is also why CNNs perform feature extraction automatically. Where traditional pipelines required an engineer to hand-specify which visual descriptors mattered, a CNN derives them from the input data during training.
Bring a new AI vision application to life.
The Building Blocks of CNN Architecture
Almost every CNN architecture is assembled from the same small set of building blocks. Data enters at the input layer, passes through hidden layers that progressively compress spatial detail while expanding semantic detail, and exits at the output layer as a prediction.
The Convolutional Layer
The convolutional layer is where representation learning happens. Each layer performs a set of convolutions in parallel, one per filter, producing a stack of feature maps. Three settings govern its behavior:
- Kernel size: the spatial extent of each filter, commonly 3×3 in modern designs.
- Stride: how far the kernel moves between positions, which controls output resolution.
- Padding: whether the border of the input is extended so that edge pixels receive equal treatment.
A nonlinear activation, usually ReLU, follows each convolution. Without it, a stack of convolutions would collapse mathematically into a single linear transformation and the depth would buy nothing.
Pooling Layers
A pooling operation downsamples each feature map, summarizing a local neighborhood into one value. Max pooling keeps the strongest response in the window, which preserves the most confident evidence of a feature. Average pooling takes the mean instead, producing a smoother signal that suits tasks where overall intensity matters more than peak response. Either way, pooling reduces the number of activations carried forward, which both lowers computation and grants the network a degree of tolerance to small shifts in object position.
Global average pooling has largely replaced large dense heads in modern designs. By collapsing each final feature map to a single value, it can reduce the number of parameters in the classification head from millions to a few thousand.
Fully Connected and Output Layers
After the convolutional stack, a fully connected layer flattens the remaining feature maps and connects every input to every output neuron. Its role is to reason over the assembled evidence rather than to look for spatial patterns. A softmax at the output layer then converts raw scores into class probabilities.

Comparing the Layer Types
| Layer | Primary Function | Learnable Parameters |
|---|---|---|
| Input layer | Accepts raw pixel tensors | None |
| Convolutional layer | Local feature extraction | Kernel weights and biases |
| Pooling layer | Spatial downsampling | None |
| Fully connected layer | Global reasoning over features | Dense weight matrix |
| Output layer | Produces class scores or coordinates | Depends on task head |
How a CNN Processes an Image Step by Step
Tracing a single frame through the network makes the abstraction concrete. Consider a 224×224 color image entering a standard classification model:
- The input layer receives the image as a 224x224x3 tensor, one channel per color. Pixel values are normalized so that no single channel dominates the early gradients.
- The first convolutional layer applies perhaps 64 kernels, producing 64 feature maps that register edges, corners, and color boundaries.
- A pooling operation halves the spatial dimensions to 112×112 while retaining all 64 channels, trading precise position for compactness.
- Successive blocks repeat the pattern. Spatial resolution shrinks, channel depth grows, and the patterns each layer detects become progressively more abstract.
- Global pooling collapses the final feature maps into a single vector that summarizes what was found rather than where.
- The fully connected layer and output layer map that vector onto class scores.
The receptive field explains why depth is necessary. A single 3×3 kernel sees nine pixels. Stack twenty with pooling in between, and a neuron near the output responds to structure spanning most of the frame. Depth is how a CNN acquires the spatial context required to distinguish a forklift from the pallet stack behind it.
How CNNs Learn
Training begins with random kernels and a loss function that quantifies the gap between prediction and label. Backpropagation computes how each weight contributed to that error, and gradient descent adjusts the weights in the direction that lowers it. In practice, mini-batch stochastic gradient descent or an adaptive optimizer such as Adam handles the update step, since computing gradients across an entire dataset at once is rarely feasible.
Managing Depth and Gradient Flow
Depth complicates this process. Gradients that pass through many layers tend to shrink or explode before reaching the earliest weights. Two interventions did most of the work in solving this. Residual connections, introduced in He et al., add a shortcut path that lets gradients bypass blocks entirely.
Batch normalization standardizes activations within each mini-batch, stabilizing the distributions that each subsequent layer receives. Monitoring model performance across both training and validation splits remains the only reliable way to tell whether a network is learning structure or memorizing examples.
Regularization and Generalization
Capacity without constraint produces a model that memorizes rather than generalizes. Most production training recipes combine several countermeasures:
- Dropout: randomly deactivates units during training so the network cannot depend on any single pathway.
- Weight decay: penalizes large weights, favoring simpler decision boundaries.
- Early stopping: halts training once validation loss stops improving, before the gap between training and validation accuracy widens.
- Learning rate scheduling: shrinks the step size as training progresses so the optimizer settles into a minimum instead of oscillating around it.
Transfer Learning as the Practical Default
Very few teams train a CNN from random initialization anymore. Transfer learning begins from weights pretrained on a large general dataset and then fine-tunes on the target task. The early layers already encode edges and textures that transfer across domains, so only the deeper layers and the task head require substantial adjustment.
The practical consequence is a sharp reduction in labeling requirements. A defect classifier that would need hundreds of thousands of examples from scratch can often reach production accuracy on a few thousand well-labeled images. That shifts the bottleneck away from data collection and toward annotation quality, which is where most timelines actually slip.
The Evolution of CNN Architectures
The current design consensus emerged through a sequence of identifiable steps:
- LeNet-5 (1998): established the convolution, pooling, and dense classification pattern for digit recognition, documented in LeCun et al. and deployed commercially to read bank checks.
- AlexNet (2012): won ImageNet using ReLU activations, dropout, and GPU training, cutting error rates sharply.
- VGGNet (2014): showed that uniform stacks of small 3×3 kernels outperform larger, shallower filters.
- GoogLeNet (2014): introduced inception modules to widen networks without proportional parameter growth.
- ResNet (2015): made networks past 100 layers trainable through residual learning.
- MobileNet and EfficientNet: optimized the accuracy-to-compute ratio for constrained hardware.
In most deployments, efficiency matters more than benchmark leadership. A model that runs at frame rate on an existing camera gateway delivers more value than one requiring a datacenter GPU, which is why lightweight computer vision models dominate edge computing for computer vision. Further reading is collected in our roundup of computer vision papers.
Convolutional Neural Networks Beyond Image Classification
Classification was only the starting point. The same convolutional backbones now serve as feature extractors for a wide range of visual tasks.
Object Detection and Segmentation
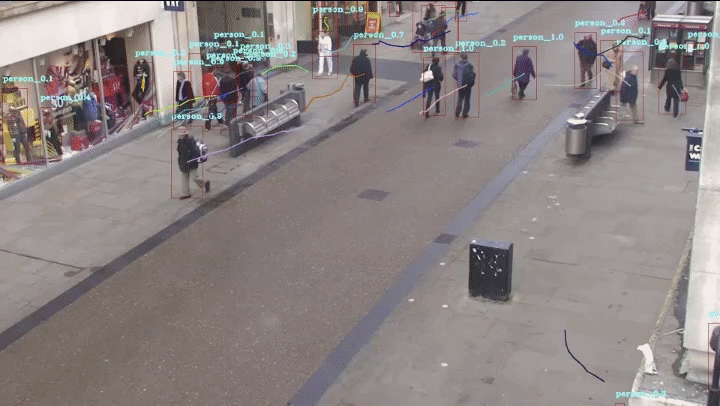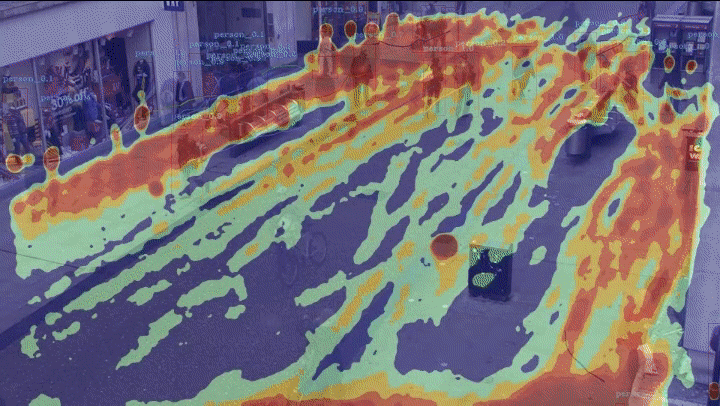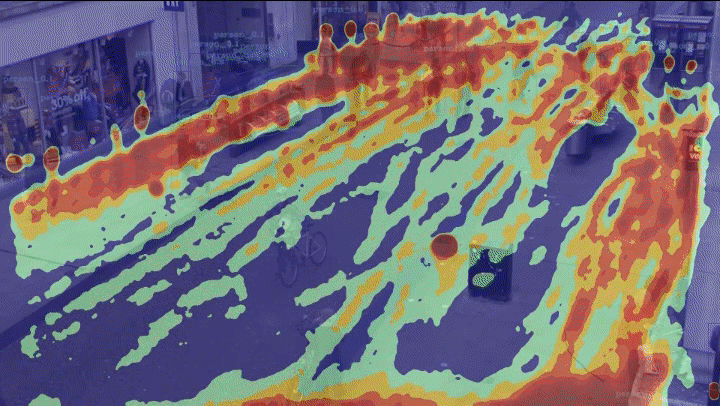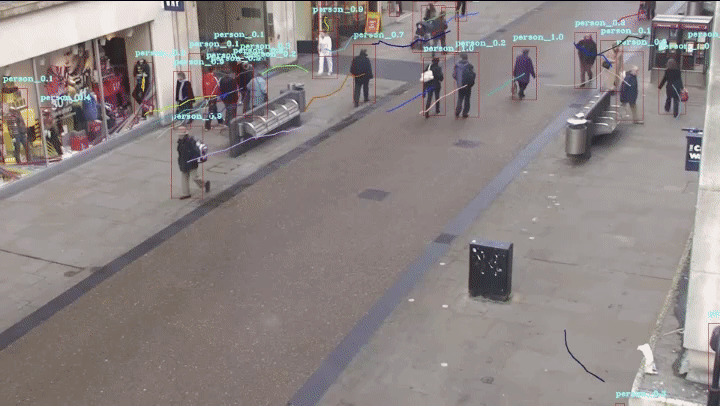
In object detection, a CNN must localize as well as label. The R-CNN family established the two-stage pattern of proposing candidate regions and then classifying them, refined into Faster R-CNN once region proposal moved inside the network.
Single-stage detectors such as the YOLO family removed the proposal step entirely, trading a small amount of accuracy for the throughput that real-time inference demands. Detection quality is scored by intersection over union against ground truth boxes and then aggregated into mean average precision, which is why precision and recall tradeoffs matter more here than headline accuracy.
Image segmentation pushes this to the pixel level. U-Net pairs a contracting encoder that captures context with an expanding decoder that restores spatial precision, an arrangement that remains the reference design for medical and industrial defect segmentation.
Temporal Understanding in Video
Video adds a dimension that 2D convolution cannot address. 3D CNNs extend kernels through time so motion becomes a learnable feature rather than a post-processing step. The Inflated 3D ConvNet approach expanded pretrained 2D filters into 3D, carrying image knowledge into video without training from scratch.
Persistent Challenges in Training CNNs
Three problems recur across nearly every real deployment.
Data scarcity and overfitting. Limited datasets invite overfitting, where accuracy on the training split diverges from accuracy on held-out data. Image data augmentation counters this by applying geometric and photometric transformations that expand effective dataset size without new labeling. Diagnosing which training errors stem from data volume rather than architecture usually determines where effort should go.
Non-grid input data. Convolution assumes a regular lattice. When relationships are irregular, graph convolutional networks generalize the operation to arbitrary connectivity, as formalized by Kipf and Welling.
Opacity. A CNN reports a class, not a rationale. Explainable AI methods such as gradient-based saliency mapping expose which regions drove a prediction, which matters in regulated settings where a decision must be defensible.
Deploying CNNs Outside the Lab
A trained model is not yet a working system. Moving a CNN onto the hardware that will run it introduces a second set of decisions, most aimed at making the network smaller and faster without degrading accuracy:
- Quantization: converts 32-bit floating-point weights to 8-bit integers, typically cutting model size by a factor of four and accelerating inference on hardware with integer units.
- Pruning: removes weights or entire channels that contribute little, which reduces the number of operations required per frame.
- Operator fusion: merges convolution, normalization, and activation into a single kernel launch to cut memory traffic.
Portability is handled through intermediate representations. ONNX provides a common graph format that multiple runtimes can consume, while toolkits such as the OpenVINO toolkit and TensorFlow Lite compile that graph for specific targets. The choice of AI hardware accelerator then sets the achievable frame rate, whether that is an NVIDIA Jetson module, an integrated GPU, or a dedicated vision processor on one of the many available edge devices.
Benchmark accuracy says little about deployed performance. Latency budget, camera placement, lighting variance, and thermal limits on the target device usually decide whether a CNN application succeeds in production.
Where CNNs Fit in Agentic Computer Vision
Attention mechanisms and the vision transformer displaced convolution as the default for large-scale pretraining, though hybrid designs that use convolutional stems ahead of transformer blocks remain common because convolution encodes locality far more cheaply than attention learns it. A useful comparison of the underlying differences is available in our breakdown of ANNs and CNNs.
The more consequential shift is architectural in a different sense. Agentic computer vision treats perception models as tools invoked by a reasoning layer that decides what to look at, which model to apply, and what action the result warrants. A CNN in that setting is no longer the system. It is a fast, reliable perceptual primitive that an agent calls when it needs a specific answer about a specific frame.
The value of a CNN in an agentic system comes precisely from its narrowness. A model that answers one visual question in milliseconds, deterministically, is a better tool than a general model that answers approximately.
This is the pattern across computer vision in manufacturing deployments built on Viso Suite, where dozens of narrow CNN detectors run against shared camera infrastructure while orchestration logic decides which outputs matter in a given context. It is also the direction physical AI systems take as they extend perception into control.