

Optical character recognition (OCR) is one of the most widely deployed and longest-established technologies in artificial intelligence, and it is evolving faster than at any point in its history. What began as a method for extracting text from a scanned document has become a foundational layer in enterprise AI systems, large language model pipelines, and automated document processing workflows that handle billions of image files every day.
This guide covers what optical character recognition OCR is, what actually happens under the hood, the best tools and systems available today, and the use cases that make this technology indispensable across industries.

What Is Optical Character Recognition (OCR)?
Optical character recognition refers to the software technology that electronically identifies printed or handwritten text inside an image, whether from a scanned document, a PDF file, a photograph, or a live video frame. It converts it into machine-readable, searchable text. OCR software is also referred to as text recognition software and, where it extends to handwriting, as intelligent character recognition (ICR).
In practical terms, OCR software enables machines to read and process information that was previously locked inside image files or physical documents, eliminating the need for manual data entry and making previously static information searchable, editable, and usable by downstream systems.
Bring a new AI vision application to life.
OCR and Intelligent Character Recognition: What Is the Difference?
Standard optical character recognition handles typed, printed text in consistent fonts. Intelligent character recognition (ICR) extends this capability to handwritten text, which varies significantly in style, size, and regularity. Modern OCR systems increasingly combine both capabilities, handling printed documents, handwritten forms, and mixed-format image files within a single pipeline.
A Brief History of OCR
The origins of optical character recognition trace back to assistive technology for the visually impaired. The foundational concept evolved through the digitization era of the late twentieth century, when OCR software became essential for converting physical archives, newspapers, legal documents, and medical records into searchable digital formats. The emergence of the internet and then smartphones extended OCR from specialized industrial applications to consumer products: mobile banking, travel apps, automated forms processing, and real-time translation all rely on OCR engines at their core.
The current phase of development is defined by the integration of OCR with machine learning and neural networks, which has dramatically expanded what systems can do and the image quality thresholds they can handle reliably.
How Does OCR Work?
Understanding how OCR works in practice requires following the pipeline from raw image input to structured text output. Modern systems process this in a sequence of stages, each of which contributes to the accuracy of the final result.
1. Image Acquisition and Pre-processing
The first stage of OCR work is acquiring the input: a scanned document, a photographed page, a PDF file, or a frame extracted from a video stream. Image quality at this stage has a direct and significant effect on output accuracy. Poor lighting, low resolution, skew, or compression artefacts in image files all introduce noise that degrades recognition performance downstream.
Pre-processing steps, such as image augmentation, address these issues systematically. Deskewing corrects rotational misalignment. Noise reduction removes dust particles, smudges, and compression artefacts. Contrast enhancement and sharpening improve the clarity of text edges.
These image quality improvements are handled automatically by modern software and are critical to achieving the high accuracy rates that enterprise OCR systems are expected to deliver.
2. Binarization
After pre-processing, the image is converted to black and white, a process called binarization. The black and white conversion assigns black or dark areas to foreground characters and white or light areas to background, creating a clean two-tone representation that simplifies character segmentation. This black and white transformation is a foundational step in traditional pipelines, though modern neural network-based OCR systems increasingly perform segmentation and recognition jointly without an explicit binarization stage.
3. Text Detection and Segmentation
The OCR engine then identifies regions of the image that contain text, separating them from graphics, whitespace, and other non-text elements. Within text regions, the engine segments individual lines, words, and characters for subsequent recognition. In scene text recognition (STR), where text appears in natural environments rather than structured documents, this segmentation stage is considerably more complex, handling variable fonts, orientations, lighting conditions, and partial occlusion.

4. Character Recognition: Pattern Recognition and Feature Detection
Character recognition is the core function of the OCR engine. Two primary approaches have been defined for how systems perform this step:
- Pattern recognition: The OCR engine compares each character against a database of known character templates, identifying the closest match. This approach works well for standard fonts in high image quality conditions but struggles with unusual typefaces or degraded input.
- Feature detection: Rather than matching whole characters, the software identifies structural features (curves, angles, strokes, intersections) and uses rules or learned models to infer the character from its components. This approach generalizes better to varied input conditions.
Modern OCR systems combine both approaches within neural network architectures. Convolutional neural networks (CNNs) extract visual features from image regions. Recurrent neural networks model sequential dependencies between characters. Transformer-based architectures, now the dominant paradigm, handle long-range dependencies and contextual disambiguation, understanding that a character that looks ambiguous in isolation has a high-probability interpretation given the surrounding text.
5. Post-processing and Accuracy Verification
After recognition, OCR systems apply post-processing to improve accuracy. Dictionary-based verification checks recognized text against known vocabulary, flagging implausible outputs for correction. Language model integration, increasingly powered by large language models, provides deeper contextual correction, resolving ambiguities that pure visual recognition cannot.
Standard accuracy benchmarks for enterprise software target 98–99% character-level accuracy on clean, well-structured input. On degraded, handwritten, or multilingual image files, accuracy varies significantly depending on the sophistication of the OCR engine and the image quality of the input.
OCR Algorithms and Neural Networks: The Current State
The integration of machine learning and neural networks has transformed what OCR systems can achieve and raised the bar for what counts as best-in-class performance.
Transformer-Based OCR
Vision Transformer (ViT) architectures now underpin the leading algorithms. TrOCR, developed by Microsoft, applies pre-trained transformer models to both the image encoding and text decoding stages, achieving state-of-the-art results on printed and handwritten text recognition benchmarks. MaskOCR extends this approach with masked pretraining, reaching 93.8% accuracy on English scene text benchmarks while using a fraction of the training data required by earlier methods.
Multimodal and LLM-Integrated OCR
The most significant recent development in OCR is its integration with large language models and vision language models. PaddleOCR 3.0, one of the most widely used open-source frameworks, has been rebuilt around LLM integration, recognizing that modern systems must not only transcribe text accurately but serve as bridges between visual and semantic AI layers. Mistral OCR 3 and similar compact models are optimized for structured document processing at enterprise scale, handling PDF files, tables, charts, and mixed-format documents with high fidelity.
This shift means that extracting text from image files is no longer the terminal output. The recognized text flows directly into downstream AI systems, retrieval-augmented generation pipelines, semantic search indexes, and document intelligence workflows, where it becomes queryable, analyzable, and actionable. Manual data entry, previously the only alternative for unstructured document data, is eliminated across entire workflows.
Open-Source OCR Systems
The open-source OCR landscape has expanded significantly. Leading open-source OCR models now include PaddleOCR, Tesseract (the longest-established open-source OCR engine), TrOCR, EasyOCR, and MiniCPM-V, each with different strengths across languages, document types, and image quality conditions. For enterprise applications, the choice of engine depends on accuracy requirements, language support, deployment environment (cloud versus edge), and the degree of integration with downstream machine learning systems.
OCR Tools: What to Evaluate
The market for OCR tools spans open-source frameworks, cloud APIs, and enterprise document intelligence platforms. When evaluating OCR software for enterprise deployment, the most important dimensions are:
- Image quality handling: How does the engine perform on degraded, low-resolution, or photographed (rather than scanned) documents?
- Language and script support: Does the software handle the languages, character sets, and scripts your documents contain?
- Layout understanding: Can the system correctly parse tables, multi-column layouts, and mixed text-and-image documents?
- PDF file handling: Does the tool process PDF files natively, including both digital-native and scanned PDFs?
- Integration with machine learning pipelines: Can the extracted text flow directly into downstream AI systems, or does it require manual reformatting?
- Processing speed: For high-volume workflows, how does the software perform at scale without becoming time-consuming?
Tesseract OCR
Tesseract is the most established open-source OCR engine, originally developed at HP and maintained by Google. It supports over 100 languages, handles a wide variety of image files including JPG, PNG, and TIFF formats, and integrates readily with Python-based machine learning pipelines. Tesseract remains a strong baseline for extracting text from clean, well-structured image files and PDF files, though it is outperformed on complex layouts and degraded input by newer neural network-based OCR systems.

Cloud-Based OCR APIs
Google Vision API, Microsoft Azure AI Document Intelligence, and Amazon Textract provide cloud-hosted OCR systems that combine optical character recognition with broader document understanding capabilities. These tools handle PDF files, scanned documents, handwritten forms, and structured document layouts, returning not just extracted text but structural metadata about document organization, table contents, and field-value pairs.
Multimodal Vision Language Models as OCR Systems
An increasingly important category of OCR tools is vision language models with strong text recognition capabilities. Models such as GPT-4o, Gemini 2.5 Pro, and Qwen3-VL can extract text from complex image files while simultaneously understanding the semantic context of the document, making them effective for tasks where text recognition and meaning extraction must happen together. For time-consuming document processing workflows that previously required separate OCR and NLP stages, these models collapse both into a single inference step.
OCR Use Cases Across Industries
Optical character recognition OCR is embedded in enterprise workflows across virtually every industry where information exists on paper or in unstructured image files. The following use cases represent the most significant deployments of OCR systems at enterprise scale.
Automatic Number Plate Recognition (ANPR)
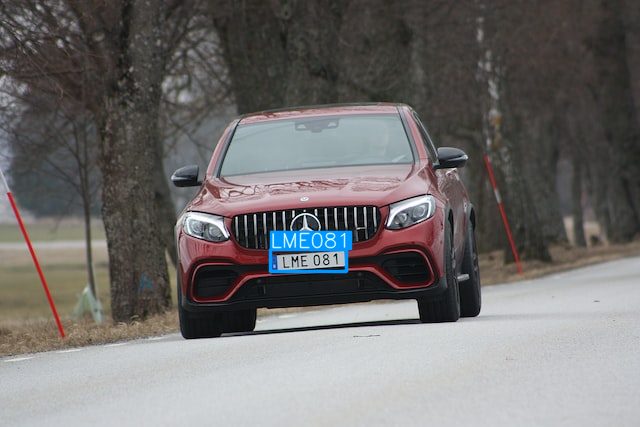
Automatic number plate recognition applies OCR engine technology to vehicle license plates in real time. ANPR systems handle highly variable image quality conditions, motion blur, partial occlusion, variable lighting, and diverse plate formats across jurisdictions, making them a demanding test case for OCR systems. Applications include access control, parking management, toll collection, and stolen vehicle detection. Scene text recognition (STR) techniques, which extend optical character recognition to natural environments with inconsistent camera conditions, are the technical foundation of modern ANPR.
Banking and Financial Services
The banking sector was among the earliest and largest adopters of OCR software. Check processing, account opening forms, and loan documentation all involve extracting text from scanned documents and image files at scale. Modern banking systems use intelligent character recognition to handle handwritten signatures and fields alongside printed text, integrating with fraud detection machine learning models that cross-reference extracted data against known patterns. Mobile deposit workflows, where a customer photographs a check with a smartphone, represent one of the most common consumer-facing applications of OCR technology.
Healthcare and Medical Records
Healthcare organizations manage enormous volumes of paper-based records (patient histories, prescriptions, lab results, insurance documents) that require digitization and indexing before they can be used in electronic health record systems. OCR software converts these scanned documents and image files into structured, searchable records, eliminating manual data entry that is both time-consuming and error-prone. In clinical environments, OCR systems are integrated with natural language processing (NLP) pipelines that extract clinical entities, diagnoses, medications, and dosages from free-text notes, enabling downstream analytics and clinical decision support.
Logistics and Transportation
Logistics operations rely on OCR systems for a wide range of document and label processing tasks. Shipping labels, customs documents, waybills, and packing lists are all processed by OCR software at intake, reducing manual data entry across warehousing and fulfilment workflows. Vehicle-mounted and fixed-position cameras apply optical character recognition OCR to container codes, pallet labels, and barcode fallback text in real time, integrating with warehouse management systems to update inventory and route shipments automatically.

Legal and Document Processing
Legal workflows involve processing large volumes of historical documents, contracts, and filings that exist only as scanned documents or PDF files. OCR tools convert these into searchable, machine-readable formats that can be indexed for e-discovery, reviewed by document intelligence systems, and processed by machine learning models that identify clauses, obligations, and risk factors. The combination of optical character recognition OCR and large language models has made AI-assisted contract review and legal document analysis practical at a scale that was previously too time-consuming to execute manually.
Scene Text Recognition (STR): OCR in the Real World
Scene text recognition extends the capabilities of traditional optical character recognition to uncontrolled environments, reading text on road signs, product packaging, billboards, digital displays, and industrial equipment labels where image quality is variable, and text appears in complex visual contexts.
Where standard OCR work assumes a structured input, such as a scanned document or PDF file, STR handles:
- Variable fonts, sizes, and orientations
- Low or uneven image quality from real-world camera conditions
- Partial occlusion of text by objects or motion blur
- Text integrated with complex visual backgrounds
- Multiple languages and scripts within a single image
Applications of scene text recognition include self-driving vehicle systems, augmented reality overlays, retail shelf analytics, and assistive technology for visually impaired users. The neural network architectures that power modern STR systems, particularly transformer-based models, handle this variability significantly better than pattern recognition approaches, which require consistent image quality and controlled input conditions to perform reliably.

Advantages of Optical Character Recognition
The benefits of deploying OCR software at enterprise scale are measurable across operational efficiency, data quality, and cost:
- Elimination of manual data entry: OCR systems convert time-consuming manual transcription into automated, high-speed text extraction, reducing both the cost and the error rate of document processing workflows.
- Improved accuracy over manual processes: Enterprise software consistently achieves extremely high character-level accuracy on clean input, outperforming sustained manual data entry on high volumes.
- Searchability and downstream AI integration: Extracting text from PDF files and image files makes previously locked information available for search, analysis, and machine learning systems (including large language models and RAG pipelines).
- Scalability: OCR systems process thousands of documents per hour without degradation in accuracy or throughput, a scale that manual data entry cannot approach.
- Regulatory compliance: Digitized, searchable records support audit trails, retention policies, and regulatory reporting requirements across industries.
What Comes Next for Optical Character Recognition
The trajectory of OCR is now inseparable from the trajectory of artificial intelligence more broadly. The integration of neural networks, large language models, and vision language models into systems has elevated optical character recognition from a document utility into a foundational layer of enterprise AI infrastructure.
Several developments are shaping the next phase of work. Multimodal OCR systems that simultaneously extract text and understand document structure, tables, charts, diagrams, and mixed-language content are replacing pipeline approaches that handled these as separate problems.
Edge deployment of compact OCR models is enabling real-time text recognition on embedded hardware in industrial and mobile environments where cloud connectivity is limited or unavailable. And the convergence of OCR with retrieval-augmented generation means that extracted text from scanned documents and PDF files flows directly into AI systems that can reason about its meaning, not just its content.
For organizations still relying on manual data entry to process document volumes that OCR software could handle automatically, the cost of inaction is growing. The technology is mature, the accuracy is enterprise-grade, and the integration with downstream artificial intelligence systems is now seamless. Optical character recognition is not a niche utility. It is the text layer that enterprise AI reads from.