

YOLOv7 arrived in July 2022 and reset expectations for what a single-stage detector could deliver on modest hardware. Several model generations later, it remains a common production choice for teams that need accuracy without a datacenter budget behind every camera stream. This guide covers how the architecture works, what its benchmark numbers actually mean, and where it sits among the wider family of object detection models available today.
What YOLOv7 Is and Why It Still Matters
YOLOv7 is a real-time object detection model released by Chien-Yao Wang, Alexey Bochkovskiy, and Hong-Yuan Mark Liao, the same lineage responsible for YOLOv4 and YOLOR. The original paper is titled “Trainable bag-of-freebies sets new state-of-the-art for real-time object detectors,” and that phrase explains the design philosophy well. A bag of freebies refers to training-time changes that raise accuracy without adding a single operation at inference.
The practical consequence is a model that trains from scratch on a single dataset, requires no ImageNet pre-trained backbone, and runs comfortably on hardware that would choke on a two-stage detector. For enterprise teams evaluating computer vision for the first time, that combination lowers the cost of a credible pilot considerably.
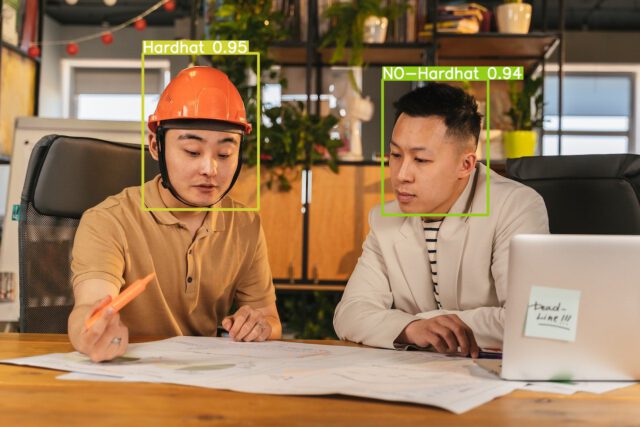
Bring a new AI vision application to life.
How YOLOv7 Fits Among Current YOLO Models
The YOLO name now covers work from several independent research groups, which makes version numbers a poor guide to lineage. YOLOv7 is the last release authored by the group that maintained the original DarkNet line, while later YOLO models come from separate business and academic teams.
| Version | Year | Authors | Peer-reviewed paper |
|---|---|---|---|
| YOLOv3 | 2018 | Redmon, Farhadi | Yes |
| YOLOv4 | 2020 | Bochkovskiy, Wang, Liao | Yes |
| YOLOv5 | 2020 | Ultralytics | No |
| YOLOv6 | 2022 | Li et al., Meituan | Yes |
| YOLOv7 | 2022 | Wang, Bochkovskiy, Liao | Yes |
| YOLOv8 | 2023 | Ultralytics | No |
| YOLOv9 | 2023 | Wang, Yeh, Liao | Yes |
| YOLOv10 | 2024 | Wang et al., Tsinghua | Yes |
| YOLOv11 | 2024 | Ultralytics | No |
| YOLOv12 | 2025 | Tian, Ye, Doermann | Yes |
| YOLO26 | 2024 | Ultralytics | Yes |
Version numbers signal release order, not architectural descent. Selecting between YOLO models should rest on measured latency and accuracy against your own footage, not on the highest available number.
Inside the YOLOv7 Architecture
Extended Efficient Layer Aggregation Network
The backbone computational block is called E-ELAN. It applies an expand, shuffle, and merge cardinality strategy that lets the network keep improving its learning capacity while leaving the original gradient path intact. Earlier aggregation designs tended to degrade gradient flow as they grew wider, which capped how much capacity could usefully be added.
Compound Model Scaling
Concatenation-based architectures cannot have their depth, width, and input resolution tuned independently, because scaling depth alters the channel ratio at every transition layer and reduces hardware utilization as a side effect. YOLOv7 addresses this with compound scaling: when the depth factor of a block changes, the output channel count changes with it, and width scaling is then applied to the transition layers at the same magnitude. The structure that was optimal at design time stays optimal after scaling.
Planned Re-parameterized Convolution
Re-parameterized convolution performs well in VGG-style networks but loses accuracy when dropped directly into residual or densely connected architectures. YOLOv7 uses RepConvN, a variant without the identity connection, wherever a layer already carries a residual or concatenation path. The result preserves the inference-time speedup without the accuracy penalty.
Auxiliary Heads and Soft Label Assignment
YOLOv7 borrows deep supervision by adding an auxiliary head that guides the middle layers during training while the lead head produces final predictions. A label assigner then generates soft labels that account for the quality and distribution of the network’s own predictions rather than deriving hard labels from ground truth alone. Both mechanisms disappear at inference, which is what qualifies them as freebies.

YOLOv7 Performance on the COCO Dataset
All published YOLO v7 results were trained on the COCO dataset without additional imagery or pre-trained weights, which makes the comparisons unusually clean. The COCO dataset, introduced in the Microsoft COCO paper, covers 80 everyday object classes across roughly 330,000 annotated images.
Reported figures from the paper, all measured on a V100 GPU, include the following. Verify each against the current paper revision before quoting externally, since the appendix tables have been updated since first publication.
- Against YOLOv4: roughly 75% fewer parameters, 36% less computation, and 1.5% higher average precision.
- Against YOLOR: roughly 43% fewer parameters, 15% less computation, and 0.4% higher average precision.
- Against comparable YOLOv5 configurations: fewer parameters at higher average precision, with YOLOv7-X reaching around 114 FPS versus 99 FPS for YOLOv5-L.
- Against Cascade Mask R-CNN: approximately 2% higher average precision at substantially faster inference.
One detail deserves attention when reading any of these numbers. Edge model comparisons in the paper were run at a batch size of 32, and batch size has a large effect on reported throughput. A larger batch size raises GPU utilization and inflates frames per second, while simultaneously increasing the latency of any individual frame. Systems that must respond to an event within a fixed window therefore often run at a batch size of one, where headline benchmark figures no longer apply. Understanding precision and recall alongside intersection over union matters more than a single FPS figure, as does ongoing model performance tracking once deployed.
Task Variants Beyond Bounding Boxes
Two official extensions broaden what the architecture handles. YOLOv7-mask pairs the detector with BlendMask for instance segmentation, fine-tuned over 30 epochs. YOLOv7-pose combines YOLOv7-W6 with YOLO-Pose for keypoint detection, supporting pose estimation for ergonomic and posture analysis.
Running Real-Time Object Detection at the Edge
A detector is one stage in a longer pipeline that runs from camera integration and image acquisition through processing, output formatting, and system integration. Moving inference close to the camera reduces bandwidth cost and removes the round trip to the cloud, which is why edge AI and edge computing for computer vision underpin most large deployments.
YOLOv7 ships in three baseline configurations aimed at different tiers of hardware:
- YOLOv7 targets ordinary GPU computing.
- YOLOv7-tiny targets edge GPUs and uses leaky ReLU rather than SiLU as its activation function.
- YOLOv7-W6 targets cloud GPU instances handling heavy deep learning workloads.
Common accelerators for this class of workload include NVIDIA Jetson modules, Google Coral Edge TPUs, and Intel vision processing units. Where CPU-only inference is the constraint, lightweight computer vision models built on MobileNet or GhostNet backbones are usually the better starting point.
From Detection to Agentic Computer Vision
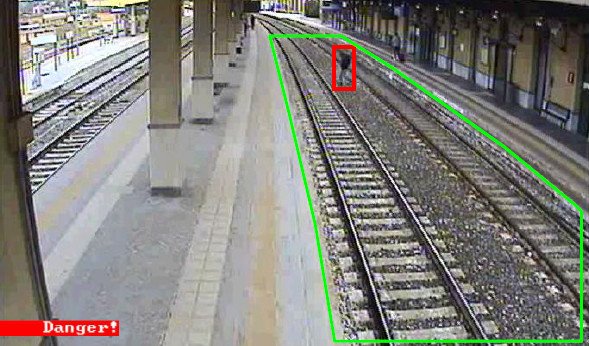
Bounding boxes answer what and where. They do not answer whether a sequence of events constitutes a hazard, or what should happen next. That gap is where agentic computer vision operates, layering reasoning and action over the detector’s raw output so that a system can interpret a scene rather than merely label it.
In these architectures, YOLOv7 functions as a fast perception primitive feeding higher-level components, including vision-language models capable of describing context and video analytics layers that reason across time. A detector flags a person in a restricted zone; an agentic layer determines whether that person is authorized, whether machinery is active nearby, and which alert routing is appropriate.
Detection accuracy sets the ceiling for everything built above it. A reasoning layer cannot recover information the perception model failed to capture, which is why fast, well-calibrated detectors remain foundational as pipelines grow more autonomous.
Where YOLOv7 Still Earns Its Place
Newer YOLO models have narrowed the advantage, and for greenfield projects a current release is usually the sensible default. YOLOv7 continues to make sense in specific circumstances:
- Licensing constraints favor its GPL-3.0 release over alternatives with different terms.
- An existing trained checkpoint and validated pipeline already meet the accuracy target.
- Training budget is limited, and no pre-trained backbone is available for the domain.
- A peer-reviewed reference is required for regulatory or procurement documentation.
