YOLOv8 is the newest model in the YOLO algorithm series – the most well-known family of object detection and classification models in the Computer Vision (CV) field. With the latest version, the YOLO legacy lives on by providing state-of-the-art results for image or video analytics, with an easy-to-implement framework.
In this article, we’ll discuss:
The evolution of the YOLO algorithms
Improvements and enhancements in YOLOv8
Implementation details and tips
Applications
Subscribe to our newsletter
Stay connected with viso.ai and receive new blog posts straight to your inbox.
YOLOv8 is no longer the newest model in the YOLO family, and that is precisely why it is worth writing about carefully. It sits in an unusual position: superseded on paper, yet still one of the most widely deployed detectors in production computer vision. Teams inherit it, extend it, and are then asked whether it is still the right choice. This guide covers what the architecture actually does, how the five model sizes trade accuracy against compute, how to train and export a checkpoint, and the licensing and operational questions that decide whether a working prototype ever becomes a working system.
What Is YOLOv8?
YOLOv8 is a single-stage object detection model released by Ultralytics on January 10, 2023. Like every model in the family, it descends from the original 2015 paper by Joseph Redmon, Santosh Divvala, Ross Girshick, and Ali Farhadi, which reframed detection as a single regression problem rather than a pipeline of region proposals and classifiers. You can read the original You Only Look Once paper for the founding argument, and our explainer on YOLO for how the idea developed.
One clarification matters before going further. Ultralytics YOLOv8 has no accompanying research paper. It was shipped as a codebase, not as a publication, which is why comparisons against peer-reviewed detectors have to be drawn from reproducible benchmark runs rather than a canonical results table.
YOLOv8 is not a single model. It is a family of five checkpoint sizes across five tasks, exposed through one interface, and that interface is the main reason it remains entrenched in production long after newer architectures arrived.
Non-maximum suppression is a post-processing step, not a pre-processing one. It runs after the network has produced its raw predictions, and its cost scales with the number of candidate boxes rather than with image size.
Computer Vision Builder
Bring a new AI vision application to life.
Turn ideas into computer vision apps — no coding needed.
Where YOLOv8 Sits in the YOLO Timeline
The lineage is longer than most summaries suggest, and the release cadence has accelerated sharply since 2023.
Later releases have continued in the same direction. The state of the art in real-time detection now sits well beyond YOLOv8, which reframes the question for most teams from “is this the best model” to “is this model good enough for the decision it feeds.”
What YOLOv8 Supports: Task and Mode
The Ultralytics interface separates two ideas that are easy to conflate. A task is what the network predicts. A mode is what you are doing with it. Every combination of task and mode uses the same command structure, which is a large part of why the framework spread so quickly.
YOLOv8 supports a wide range of computer vision tasks rather than detection alone:
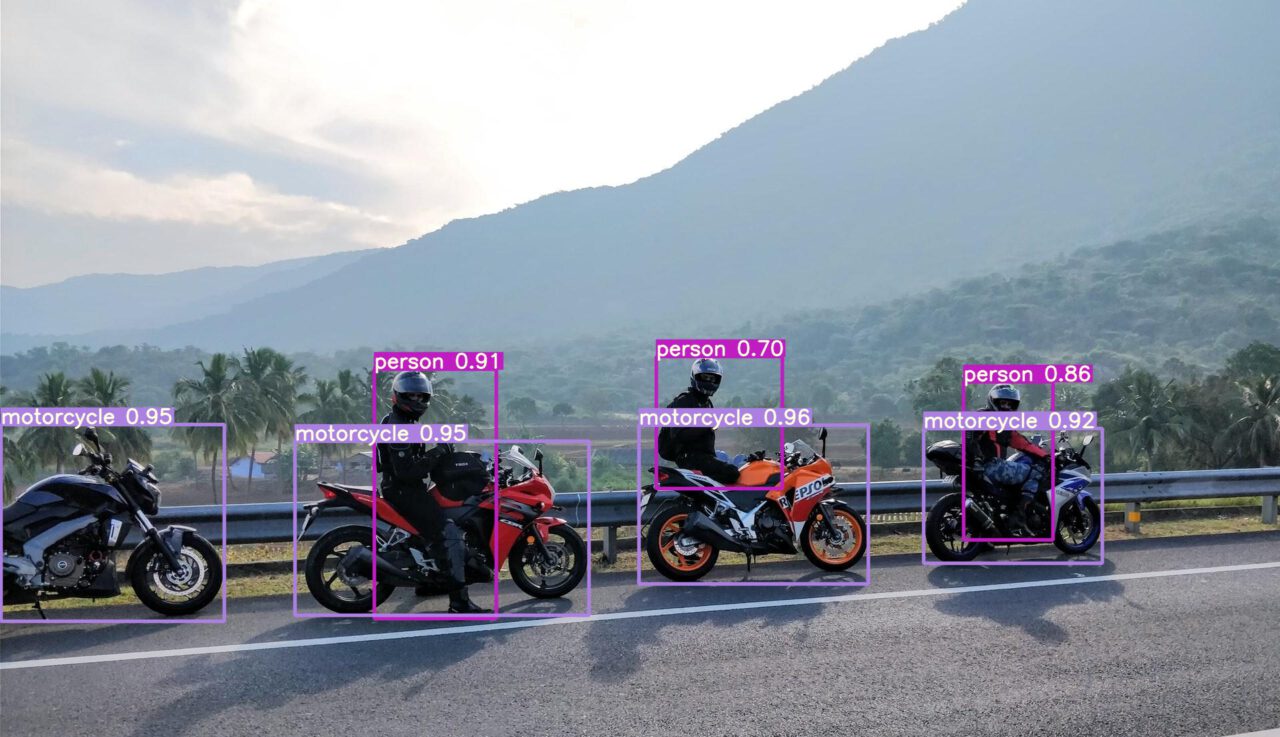
Object detection returns an axis-aligned bounding box, a class label, and a confidence score
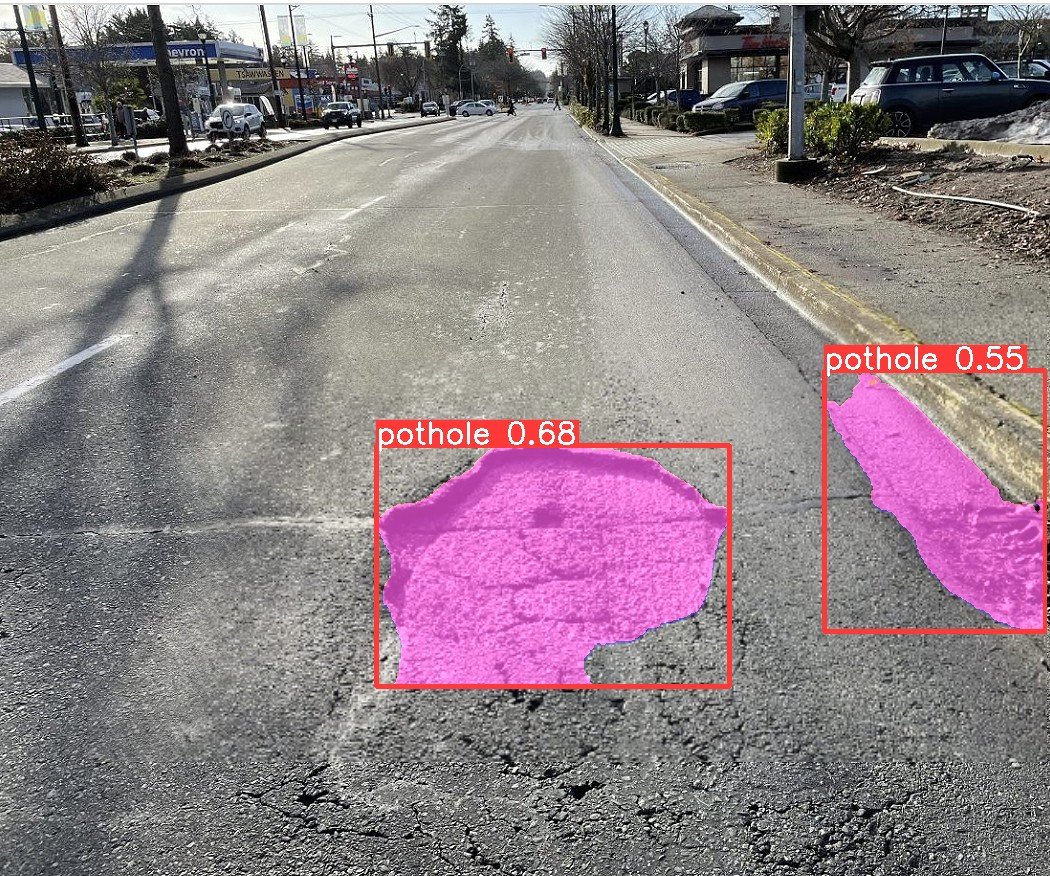
Instance segmentation adds a per-pixel mask, distinguishing it from semantic segmentation, which does not separate individual objects
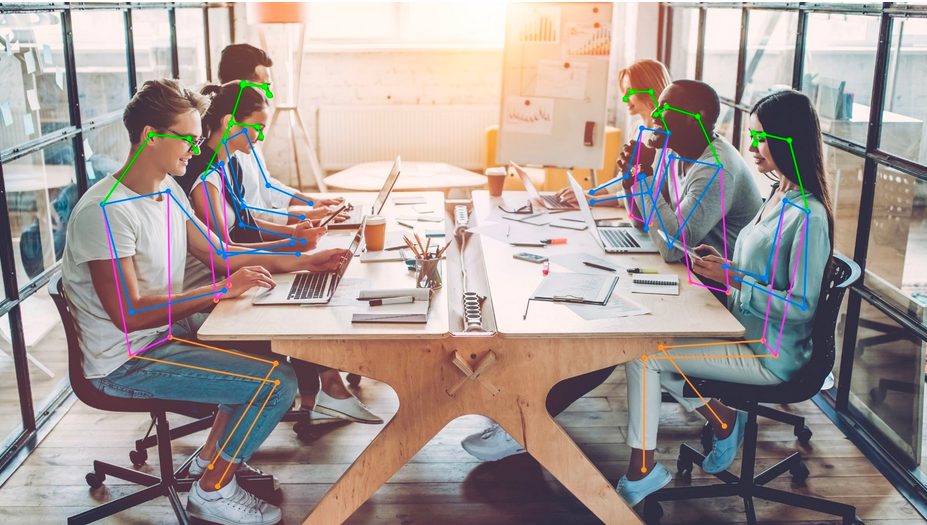
Pose estimation predicts 17 COCO keypoints per detected person
Oriented detection predicts a rotated box, which matters for aerial imagery and densely packed shelving
The modes are train, val, predict, export, track, and benchmark. Track mode requires a localized output, so it wraps every task except classification. The earlier version of this article listed only three tasks, which understated the framework considerably.
Checkpoint suffixes are the only thing that changes between tasks. A team already running detection can add pose estimation without touching its inference wrapper, which is why suffix conventions are worth documenting internally.
YOLOv8 Model Sizes and How the Models Perform
YOLOv8 ships in five model sizes: nano, small, medium, large, and extra large. The five YOLOv8 models are the same architecture at different depth and width multipliers, so they share one training recipe and one export path. All figures below are single-model, single-scale results on COCO val2017 at 640 pixels, measured on an Amazon EC2 P4d instance.
Model
mAP 50-95
Params (M)
FLOPs (B)
A100 TensorRT (ms)
YOLOv8n
37.3
3.2
8.7
0.99
YOLOv8s
44.9
11.2
28.6
1.20
YOLOv8m
50.2
25.9
78.9
1.83
YOLOv8l
52.9
43.7
165.2
2.39
YOLOv8x
53.9
68.2
257.8
3.53
How the models perform across that range is more interesting than any single number. Moving from nano to extra large multiplies parameters by roughly 21 and FLOPs by roughly 30, while mAP rises 16.6 points. Almost 78 percent of that accuracy gain is captured by the time you reach the medium checkpoint. Everything above it buys diminishing returns at steeply rising cost, which is the calculation that matters when inference runs on Jetson-class hardware rather than a datacenter GPU.
For real-time object detection workloads, the useful question is not which checkpoint scores highest, but which one clears the accuracy bar inside the available latency budget.
Benchmark scores also describe performance on COCO, not on your cameras. Our guide to model performance covers why validation mAP and deployed accuracy diverge, and intersection over union explains the threshold these numbers depend on.
The Architecture Changes That Mattered
Three changes separate YOLOv8 from its predecessor, and each has a practical consequence rather than only an academic one.
Anchor-Free Bounding Box Prediction
Earlier YOLO versions matched predictions against predefined anchor boxes tuned to a dataset’s typical object shapes. That tuning transfers badly. Anchor-free prediction has the model estimate an object’s center directly, which reduces the number of candidate boxes and shortens non-maximum suppression. For custom datasets with unusual aspect ratios, industrial pallets, long tools, or vehicles seen obliquely, it removes a class of failure that used to require manual anchor recalculation.
The C2f Backbone Module
The backbone replaced the C3 module with C2f. The difference is narrow but real: C2f concatenates the outputs of every bottleneck block rather than only the last one, improving gradient flow through the convolutional network during training. The bottleneck blocks themselves are residual in construction.
The Decoupled Head and Task Alignment
Classification and box regression run on separate branches. Separating them removes a gradient conflict, but introduces the risk that the model localizes one object while classifying another. YOLOv8 resolves this with a task alignment score, multiplying the classification score by the IoU score to select the top-k positive samples. The approach follows the TOOD task alignment learning paper. Box regression is optimized with complete IoU loss alongside distribution focal loss, introduced in the Generalized Focal Loss paper, which models box boundaries as a distribution rather than a single point estimate.
Training a YOLOv8 Model
Installation is a single command, and the same arguments work from the command line or from Python.
pip install ultralytics
Command Line
The yolo command takes a task and mode, a model, and any arguments you want to override. Running prediction against a hosted sample image confirms the install works end to end:
The Python surface mirrors the CLI. This example loads a pretrained checkpoint, trains the model on the COCO8 dataset for 100 epochs, validates it, runs inference, and exports the result:
from ultralytics import YOLO

# Load a pretrained YOLOv8 nano checkpoint
model = YOLO("yolov8n.pt")

# Train the model on the COCO8 dataset for 100 epochs
model.train(data="coco8.yaml", epochs=100, imgsz=640)

# Validate and inspect metrics
metrics = model.val()

# Run inference on a local image
results = model("path/to/image.jpg")
results[0].show()

# Export the model to ONNX format for deployment
path = model.export(format="onnx")
COCO8 is a deliberately tiny eight-image dataset used to verify that a training loop runs. Replace it with your own YAML file before drawing any conclusions from the numbers.
Exporting for Deployment
Exporting the model to ONNX format decouples it from PyTorch, which is usually a prerequisite for edge deployment. Our ONNX explainer covers the interoperability argument, and lightweight model selection covers what survives the conversion.
Export format changes the effective latency ranking of the model sizes. A checkpoint that looks slow in PyTorch may sit comfortably inside budget once quantized, so size selection should follow export benchmarking rather than precede it.
The Enterprise License Question
This is the part most technical guides omit, and it stops more industrial deployments than any accuracy figure.
Ultralytics distributes YOLOv8 under AGPL-3.0. That license covers both the training code and the weights produced by it, so a checkpoint you fine-tuned on your own proprietary footage is still AGPL-3.0. Using it inside a private internal tool, or in a customer-facing product where you do not intend to publish your source, triggers the requirement for an Ultralytics Enterprise License.
A fine-tuned model trained on your own data does not become your own license. Internal-only use is not an exemption under AGPL-3.0, and this catches a large number of enterprise pilots at the point of rollout rather than at the point of selection.
The practical implication is that model choice and license choice have to be made together. Teams that discover this after building six months of integration around a specific checkpoint face either an unplanned procurement cycle or a migration. Our overview of AI licenses covers the broader landscape, and permissively licensed alternatives exist if open-sourcing your stack is not acceptable.
Where YOLOv8 Fits in an Operational Stack
A detector returns boxes. An operation needs decisions, and the distance between those two things is where most projects stall. YOLOv8 is stateless: it has no memory of the previous frame, no concept of a zone, and no notion of whether the same forklift has now been counted eleven times.
Closing that gap requires object tracking for identity across frames, spatial and temporal rules to convert detections into defined conditions, aggregation into metrics a site manager can act on, and drift monitoring to catch the slow degradation caused by seasonal light and changing layouts. This is the layer Viso Suite provides, and it is also the reason computer vision projects fail far more often at integration than at model selection.
The detector is the most replaceable component in an industrial vision deployment, and the one teams spend the most time evaluating. Integration, rules, and oversight layers absorb the majority of the effort and almost none of the attention
YOLOv8 and Agentic Computer Vision
Detectors like YOLOv8 are increasingly used as perception primitives beneath a reasoning layer rather than as complete systems. In agentic computer vision, a fast bounding box detector runs continuously and cheaply, while a slower vision language model is invoked only on the frames the detector flags as interesting.
That division of labor plays to YOLOv8’s strengths. It is small, predictable, and cheap enough to run on every frame, which is exactly what a triage layer needs. The reasoning above it handles ambiguity, context, and the queries a fixed class list cannot answer.
Key Takeaways
YOLOv8 covers five tasks and five model sizes through one interface, and that consistency explains its staying power better than its benchmark scores do
Accuracy gains flatten sharply above the medium checkpoint, so default to the smallest model that clears your accuracy bar
AGPL-3.0 applies to weights you trained yourself, and internal use is not exempt
Newer YOLO releases outperform it on COCO, so treat version choice as a deployment decision rather than a leaderboard decision
The detector is one layer of seven, and the other six determine whether the deployment produces anything usable