

Object detection is the computer vision task of finding what is in an image and where it sits, and few models shaped that field as decisively as YOLOv3. Released in April 2018 by Joseph Redmon and Ali Farhadi, it arrived as a deliberately modest update to an already popular architecture, and it became the version that thousands of production systems standardized on.
Now, YOLOv3 occupies an unusual position. It is no longer state of the art, yet it has not disappeared. Frozen weights, a permissive toolchain, and predictable behavior on modest hardware keep it running in factories, farms, and traffic systems long after newer detectors overtook it on benchmark tables. This guide explains how the model works, what it actually changed, how to run it today, and how to judge whether it still belongs in your stack.

What Is YOLOv3?
YOLOv3 is a single-stage object detection model that identifies and locates objects in images, video files, and live camera feeds. It is the third and final version authored by the original YOLO team, and Redmon and Farhadi published it as a technical report titled YOLOv3: An Incremental Improvement.
The lineage matters. Redmon, Santosh Divvala, Ross Girshick, and Ali Farhadi introduced the first version in the 2015 paper You Only Look Once: Unified, Real-Time Object Detection, presented at CVPR 2016. YOLOv2 followed in late 2016, and YOLOv3 closed the original series in 2018. Every YOLO release after that came from other research groups and companies.
Bring a new AI vision application to life.
Why the Name “You Only Look Once”?
The name is often explained incorrectly, including in older tutorials that attribute it to the model’s use of 1×1 convolutions. That is not where it comes from.
You Only Look Once (YOLO) refers to the fact that the model needs a single forward pass through one neural network to produce every detection in an image. Earlier detectors such as R-CNN and Fast R-CNN worked in stages: propose candidate regions, then run a classifier over each one, often thousands of times per image. YOLO replaced that pipeline with one network evaluation, which is precisely what made real-time object detection practical.
The “once” in You Only Look Once describes the number of network evaluations per image, not the kernel size of any layer. A single pass over the full frame also means every prediction is informed by global context rather than by an isolated crop.
How YOLOv3 Works
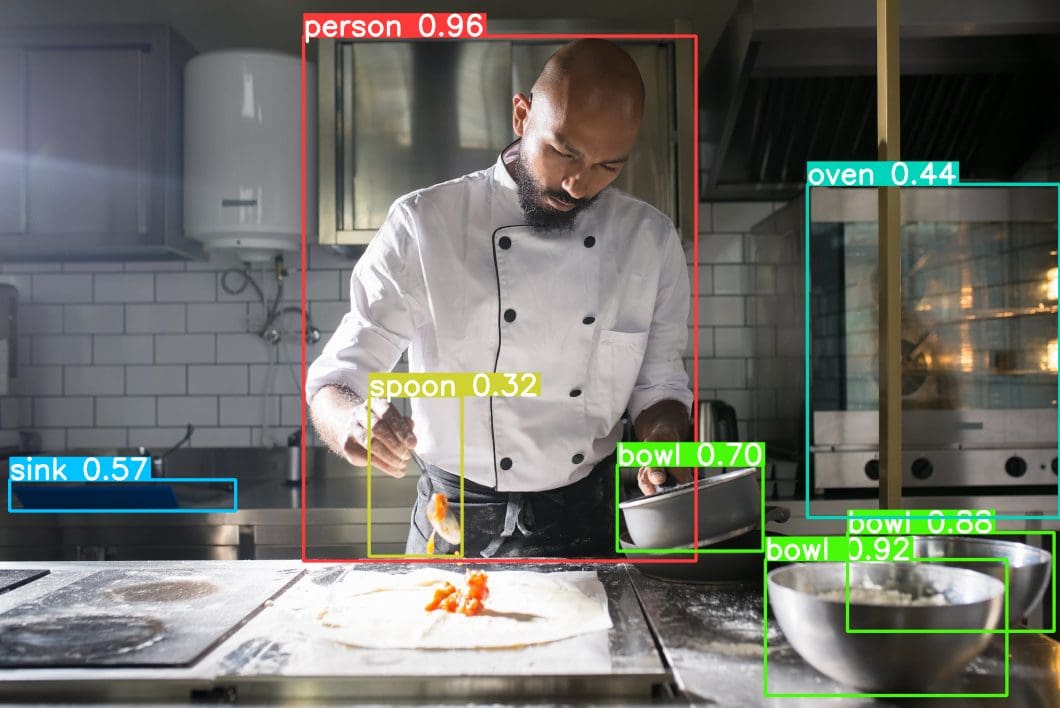
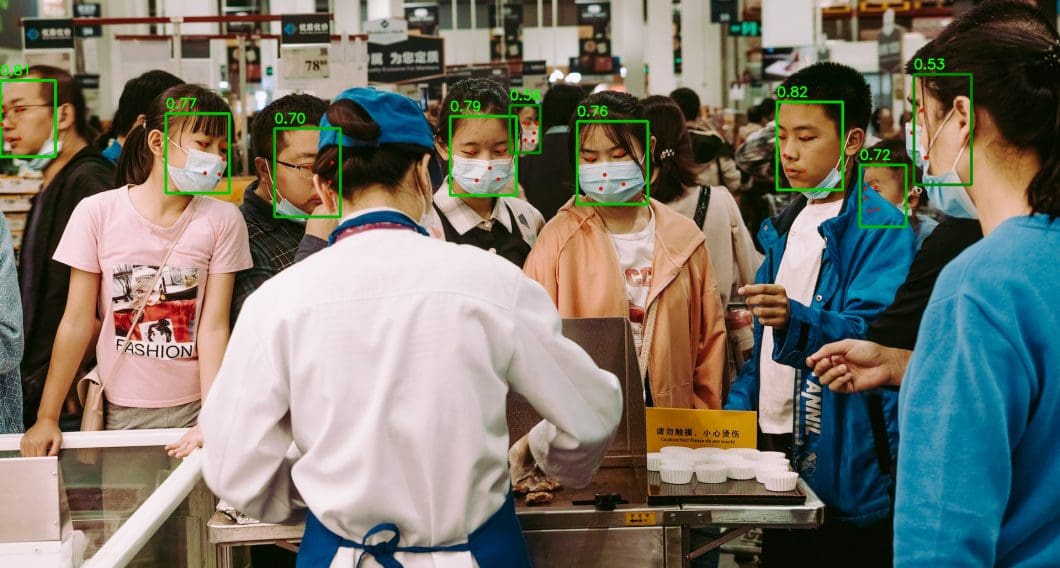
YOLOv3 divides an input image into a grid and asks each grid cell to predict a fixed number of bounding boxes, along with a confidence score and class probabilities for each box. Confidence expresses two things at once: whether an object is present, and how well the predicted box overlaps the true extent of that object.
Because the model sees the whole frame at once, it makes fewer false detections on empty background than region-proposal methods. The trade-off is coarser localization, which YOLO v3 addressed by predicting at multiple resolutions.
Detections are then filtered in two steps. A confidence threshold removes weak predictions, with the reference implementation defaulting to 0.25. Non-maximum suppression then removes duplicates by keeping the highest-scoring box in any cluster of overlapping boxes and discarding the rest, judged by intersection over union.
The YOLOv3 Architecture at a Glance
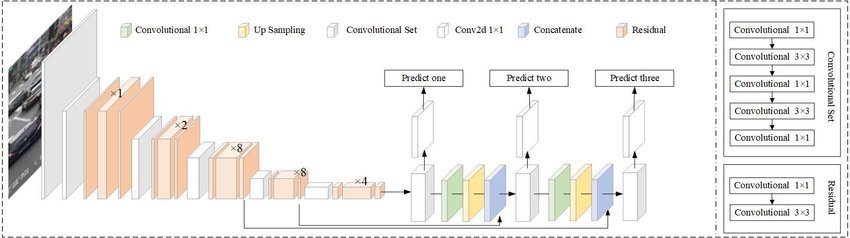
Three design choices account for most of what separates YOLOv3 from its predecessor: a deeper backbone, prediction at three scales, and a change in how class labels are handled.
Darknet-53, the Feature Extractor
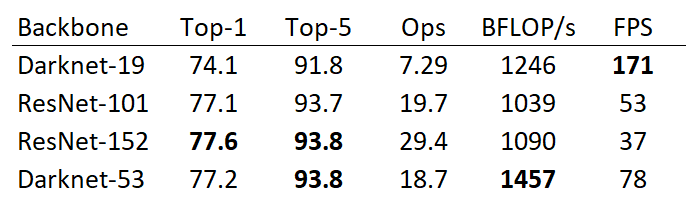
YOLOv2 used Darknet-19 as its backbone. YOLOv3 replaced it with Darknet-53, a feature extractor with 53 convolutional layers and residual shortcut connections borrowed from ResNet. Those shortcuts are what allow the extra depth to help rather than hurt, since gradients can bypass blocks during training.
The paper reports that Darknet-53 matches ResNet-152 on ImageNet classification accuracy while running roughly twice as fast, and beats ResNet-101 while running about 1.5 times faster. The gain comes from better use of the GPU rather than from fewer operations.
Anchor Boxes and Multi-Scale Prediction
YOLOv3 does not regress box coordinates from nothing. It predicts offsets relative to reference shapes called anchor boxes, obtained by k-means clustering the width and height of ground truth boxes in the training data. Predicting a small correction to a sensible prior is a far easier learning problem than predicting absolute dimensions.
The model uses nine anchor boxes in total, divided across three detection heads that operate at three different resolutions. Each cell at each scale predicts three boxes, so one anchor box shape is assigned per cell per scale.
The coarse head detects large objects. For the finer heads, the network upsamples its deep feature map and concatenates it with an earlier feature map from further back in the backbone, combining high-level semantics with spatial detail that survives only in shallower layers. This is what made detecting objects of varying scale within one frame workable, and it accounts for the largest accuracy gain in the release.
Class Prediction and the Loss Function
YOLOv2 used a softmax over classes, which forces every box into exactly one category. YOLOv3 replaced it with independent logistic classifiers trained under binary cross-entropy, so the loss function treats each class as a separate yes-or-no question.
That change enables multi-label prediction. A dataset like Google’s Open Images contains overlapping labels such as “man” and “person,” and a softmax cannot represent a box that is correctly both. Independent classifiers can. Note that class counts are dataset properties, not architectural ones: the same configuration trained on Pascal VOC predicts 20 classes, and trained on COCO it predicts 80.
What YOLOv3 Actually Changed
The title of the paper is not false modesty. YOLOv3 is an incremental improvement in the literal sense: no single breakthrough, several compounding refinements. The headline result was accuracy on small objects, where YOLOv2 had been genuinely weak.
Measured on COCO at the stricter multi-threshold metric, average precision for small objects rose from 5.0 in YOLOv2 to 18.3 in YOLOv3. RetinaNet still led on overall average precision, and the YOLOv3 authors were candid that their model traded some precision for speed.
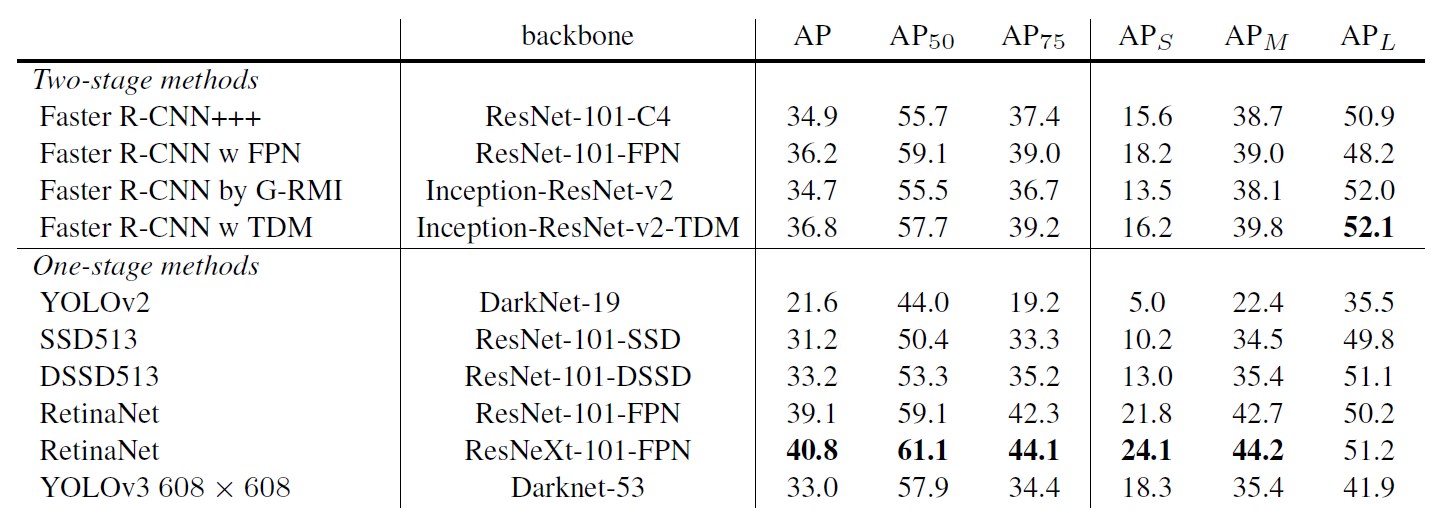
The speed story is where YOLOv3 earned its reputation. At the older mAP@50 metric, it was competitive with the best detectors available while running several times faster. These are the figures published by the authors on COCO test-dev with a Pascal Titan X:
| Configuration | mAP@50 | Billion FLOPs | FPS |
|---|---|---|---|
| YOLOv3-320 | 51.5 | 38.97 | 45 |
| YOLOv3-416 | 55.3 | 65.86 | 35 |
| YOLOv3-608 | 57.9 | 140.69 | 20 |
| YOLOv3-tiny | 33.1 | 5.56 | 220 |
| RetinaNet-101-800 | 57.5 | not reported | 5 |
Two details in that table still shape deployment decisions. Input resolution is a runtime setting, so the same weights can be traded between speed and accuracy without retraining. And YOLOv3-tiny reaches 220 FPS for roughly 4 percent of the compute of the full model, which is why it remains a common choice on constrained edge devices.
Running YOLOv3 With a Pre-Trained Model
Much of the installation advice online is wrong. There is no official pip install yolov3 package from the original authors, and instructions that begin there will not produce the reference implementation. YOLOv3 ships as part of Darknet, a framework written in C and CUDA, and you build it from source.
The original walkthrough is still published at https://pjreddie.com/darknet/yolo/, and the historical commands are these:
- Clone and build the framework. Run
git clone https://github.com/pjreddie/darknet, thencd darknetandmake. Building with OpenCV and CUDA enabled is what unlocks live video and GPU inference. - Download the weights. The COCO pre-trained model is a single 237 MB file:
wget https://data.pjreddie.com/files/yolov3.weights. Configuration files already sit in thecfg/directory. - Run the detector. Use
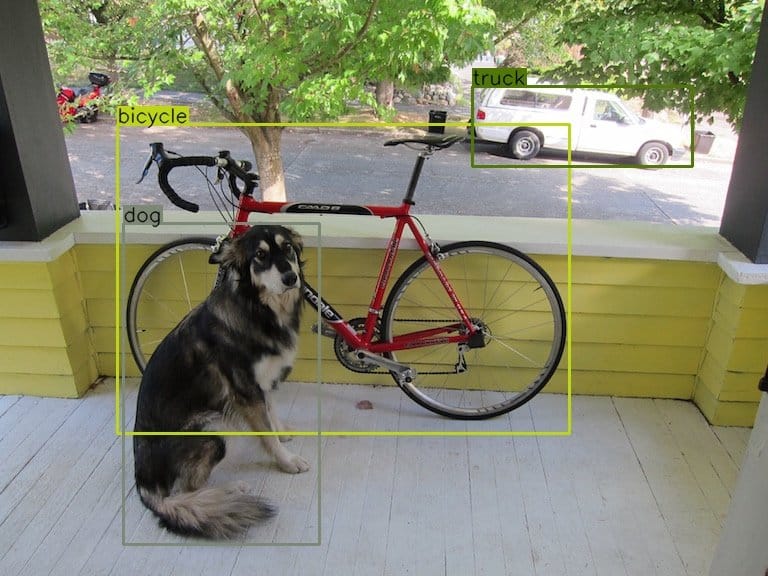
./darknet detect cfg/yolov3.cfg yolov3.weights data/dog.jpg. Adjust sensitivity with the-threshflag, and swap inyolov3-tiny.cfgwith its matching weights for constrained hardware.
Those commands target the original repository, which is effectively frozen. For anything beyond reproducing a 2018 result, use the maintained fork described in the next section instead.
Train the Model on a Custom Dataset
Pre-trained COCO weights are a demo, not a solution. Any real application needs domain-specific training, and for YOLOv3 that means four things: labeled images in Darknet’s annotation format, a .data file pointing at your train and validation lists, a .cfg file edited for your class count, and ImageNet-pre-trained backbone weights as a starting point.
The filter arithmetic catches most newcomers. In each convolutional layer immediately preceding a detection head, the filter count must equal (number of classes + 5) x 3. Get it wrong and training fails in ways that look like data problems. Quality of image annotation then dominates everything else, since most disappointing results trace back to labels rather than to training configuration.
What Happened to Darknet
This is the part of the YOLOv3 story that most articles have not updated, and it changes the practical calculus considerably.
The original pjreddie/darknet repository has not been meaningfully maintained for years. Alexey Bochkovskiy’s fork carried development from roughly 2017 to 2021 and is also dormant. Since 2023 the active lineage has been maintained by Stéphane Charette with sponsorship from Hank.ai, and in August 2025 that project moved to Codeberg, with commits mirrored to its former GitHub home.
That fork is not a preservation project. It has been converted to C++ with a unified CMake build across Linux, Windows, and macOS, gained AMD ROCm support alongside CUDA, added experimental ONNX export, and fixed builds for NVIDIA Jetson Orin hardware. Version 5.1 shipped in December 2025 and retains compatibility with existing YOLOv3 configuration and weights files.
The maintained Darknet is licensed under Apache 2.0 and can be embedded in commercial products without a fee. Ultralytics releases, including YOLOv8 and YOLO26, ship under AGPL-3.0, which imposes source-disclosure obligations on networked deployments unless a commercial license is purchased. For some organizations this licensing difference outweighs several points of mAP.
Where YOLOv3 Still Fits
Choosing YOLOv3 in 2026 is defensible in specific circumstances, and indefensible in others. The honest version of the decision looks like this.
Reasonable reasons to stay:
- An existing deployment is validated, documented, and performing to specification, and the cost of requalification exceeds the benefit of newer accuracy.
- Licensing constraints rule out AGPL-3.0 models and a permissively licensed C or C++ runtime is a hard requirement.
- The target hardware is old enough that modern frameworks will not build on it cleanly.
- Reproducibility matters more than peak performance, as in regulated or forensic settings where a frozen model must return identical output for identical input.
Reasons to migrate:
- You are starting a new project. Newer detectors reach comparable accuracy at a fraction of the parameters, and lightweight architectures have advanced substantially since 2018.
- Small or densely packed objects dominate your data, where YOLOv3 remains the weakest of the modern lineage.
- You need segmentation, keypoints, oriented boxes, or tracking, none of which YOLOv3 provides.
- Your team lacks anyone comfortable debugging a C build, which is a real operational risk rather than a stylistic preference.

YOLOv3 in Agentic Computer Vision Systems
The move toward agentic computer vision has changed how detectors get used rather than making them obsolete. In these systems, a reasoning layer, typically a vision language model, interprets a scene, decides what to check, and calls specialized perception tools for the answers.
Detectors occupy the tool layer. What a reasoning layer needs there is not maximum accuracy but bounded latency, a stable output contract, and behavior that does not drift between releases. A model whose weights have not changed since 2018 satisfies the last requirement absolutely, which is an odd form of currency for an old architecture to hold.
The constraint is capability. YOLOv3 returns axis-aligned bounding boxes over a fixed vocabulary fixed at training time, so it cannot answer open-vocabulary queries that an agent may generate at runtime. In practice, it functions as a cheap, deterministic confirmation step beneath a more flexible model, not as the component that decides what to look for.
YOLOv3 vs. Newer YOLO Versions
The YOLO name has passed through many hands since 2018, and the versions are not a single coherent series:
- YOLOv4: Bochkovskiy, Wang, and Liao, April 2020
- YOLOv5: Ultralytics, May 2020, released without an accompanying paper
- YOLOR and YOLOX: 2021
- YOLOv6: Meituan, June 2022
- YOLOv7: Wang, Bochkovskiy, and Liao, July 2022
- YOLOv8: Ultralytics, January 2023, the first widely adopted anchor-free release
- YOLOv9 and YOLOv10: 2024
- YOLO11: Ultralytics, September 2024
- YOLOv12: Tian, Ye, and Doermann, February 2025, attention-centric
- YOLOv13: Tsinghua University and iMoonLab, June 2025, detection only
- YOLO26: Ultralytics, January 2026, with end-to-end inference that removes non-maximum suppression entirely
Two architectural shifts separate YOLOv3 from everything recent. Anchor-free heads, mainstream since YOLOv8, drop the anchor box priors YOLOv3 depends on, and NMS-free designs eliminate the post-processing step described earlier, removing a source of latency variance. Together they make migrating off YOLOv3 a re-engineering exercise rather than a weight swap. To learn more about the YOLO series, check out our YOLO Explained: From v1 to Present blog.
Deploying Object Detection at Scale
Selecting a detector is the smallest decision in a computer vision project. Annotation, training infrastructure, versioning, edge deployment, and drift monitoring determine whether a working model becomes a working system.
Viso Suite provides that infrastructure as a single platform, covering the full application lifecycle and supporting YOLOv3 alongside current architectures, with on-device inference that keeps video data off the cloud.
To see how it fits your environment, request a demo with our team.